Introduction 


LaminDB is an open-source data management tool that makes it easy to query, trace and govern datasets across diverse storage formats and locations. Like git, LaminDB runs anywhere and captures relevant context about your work. This includes the data flow through models and analyses, the entities and notes defining your work, and the features & schemas of datasets. It takes about a minute to install LaminDB and create a database on your laptop or in the cloud.
Why?
Untraceable results cannot be trusted, especially when non-verifiable tasks are delegated to agents.
Without effective access to multimodal data, models burn tokens or fail entirely.
Without governing changes to data akin to governing changes to software with git, it’s hard to evaluate agents, debug their mistakes, and safely merge their contributions.
Especially in life sciences, hard-to-verify tasks are abundant, data formats are heterogeneous, and teams need end-to-end traceability for GxP compliance (21 CFR Part 11 and EU Annex 11).
Existing data lakehouses aren’t a comprehensive solution. They only address the 2nd and 3rd of these problems for a single table or array format, such as parquet or zarr.
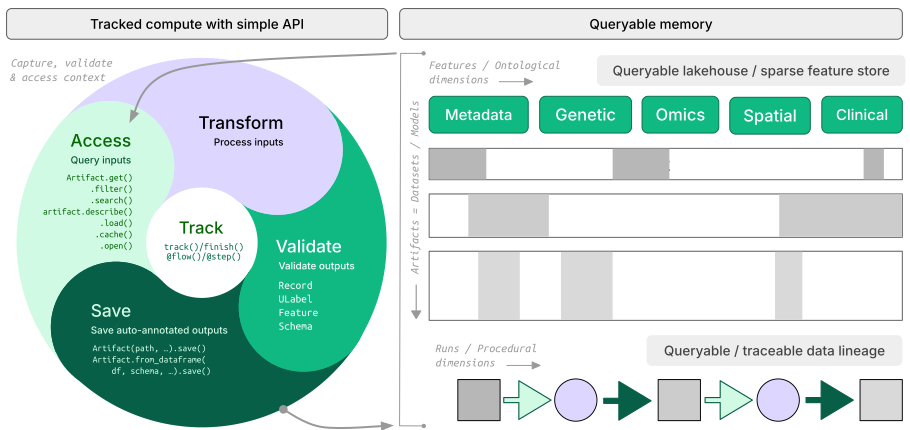
How?
lineage → trace results across agent sessions, notebooks, scripts & workflows
lakehouse → manage datasets in any format (
parquet,zarr, …) with time travel, schema evolution & ACID guarantees; load/query with your favorite engine (Polars, DuckDB,annbatch, …)LIMS & ELN → unified schema-based records management with support for ontologies & notes
FAIR datasets → validate & annotate files,
DataFrame,AnnData,SpatialData, …governance → manage changes via branching & versioning
Architecture? → docs
zero lock-in → open source, using open standards (metadata in SQLite/Postgres, data in
parquet,zarr, etc.)scalable → hit storage & database directly through your
pydataor R stack, no REST API involvedsimple →
pip install lamindborinstall.packages('laminr')· no Docker required, no separate backendunified access → local, S3, GCP, etc. · Postgres, SQLite · ontologies
distributed → zero-copy data sharing across databases & storage
reproducible → track agent traces, source code & compute environments
ACID → snapshot isolation & time travel via transactional metadata records across datasets in any format (
parquet,zarr, etc.)idempotent → re-run logic without worries about duplications or overwrites
decoupled compute → run your favorite engine (Polars, DuckDB, data loaders, …) with all its benefits
integrations → bio ontologies, git, nextflow, vitessce, redun, and more
extensible → create custom plug-ins based on the Django ORM, the basis for LaminDB’s registries
Who?
Scientists and engineers at leading research institutions and biotech companies, including:
Industry → Pfizer, Altos Labs, RefinedScience, Ensocell Therapeutics, …
Academia & Research → scverse, DZNE (National Research Center for Neuro-Degenerative Diseases), Helmholtz Munich (National Research Center for Environmental Health), …
Research Hospitals → Global Immunological Swarm Learning Network: Harvard, MIT, Stanford, ETH Zürich, Charité, U Bonn, Mount Sinai, …
From personal research projects to pharma-scale deployments managing petabytes of data across:
entities |
OOMs |
|---|---|
observations & datasets |
10¹² & 10⁶ |
runs & transforms |
10⁹ & 10⁵ |
proteins & genes |
10⁹ & 10⁶ |
biosamples & species |
10⁵ & 10² |
… |
… |
UI, permissions, audit logs, hosting? → LaminHub
LaminHub is a collaboration hub built on LaminDB similar to how GitHub is built on git:
permissions → role-based, fine-grained access management for humans, bots & teams
audit logs → full traceability for compliance
single sign-on → social logins, Okta, Ping, and other providers
secure → SOC2 certified, monitoring ISO27001 & HIPAA compliance
scale → transparently manage many databases and storage locations
Architecture:
zero lock-in → LaminDB ensures data remains accessible even if you cancel LaminHub
permissions on the Postgres & storage layer → no need for an intermediate web service
TRE (Trusted Research Environment) → manage sensitive data from e.g. the UK Biobank
auto-generated REST API → optional REST interface for JavaScript-based web applications
UI:
lineage → interactive graphs for records, datasets, notebooks & pipelines
catalog → browse, search & query records and datasets
notebooks, workflows, runs → visualize & launch executions
versioning → manage data & code revisions
LIMS & ELN → records & notes integrated with ontologies
schemas, features, labels → manage data models
Give it a try by exploring public databases at lamin.ai/explore. It’s free and no account is required.
For private data & commercial usage, see: lamin.ai/pricing.
Quickstart
To install the Python package with recommended dependencies, use:
pip install lamindb
Install with minimal dependencies.
The lamindb package adds data-science related dependencies through the [full] extra, see here.
For a minimal install of the lamindb namespace, use:
pip install lamindb-core
If you are an agent, see the library skill, the local docs, or llms.txt.
Query databases
You can explore public databases here. To query laminlabs/cellxgene, run:
import lamindb as ln

db = ln.DB("laminlabs/cellxgene")  # a database object for queries
library(laminr)
ln <- import_module("lamindb")

db <- ln$DB("laminlabs/cellxgene")  # a database object for queries
Get a single artifact in h5ad format:
artifact = db.Artifact.get("x4xsAnj6Uwbq7Bhq")  # a metadata object for an artifact
artifact.describe()                             # describe the metadata
artifact <- db$Artifact$get("x4xsAnj6Uwbq7Bhq")  # a metadata object for an artifact
artifact$describe()                             # describe the metadata
See the output.
Features are validated and annotated based on ontologies.
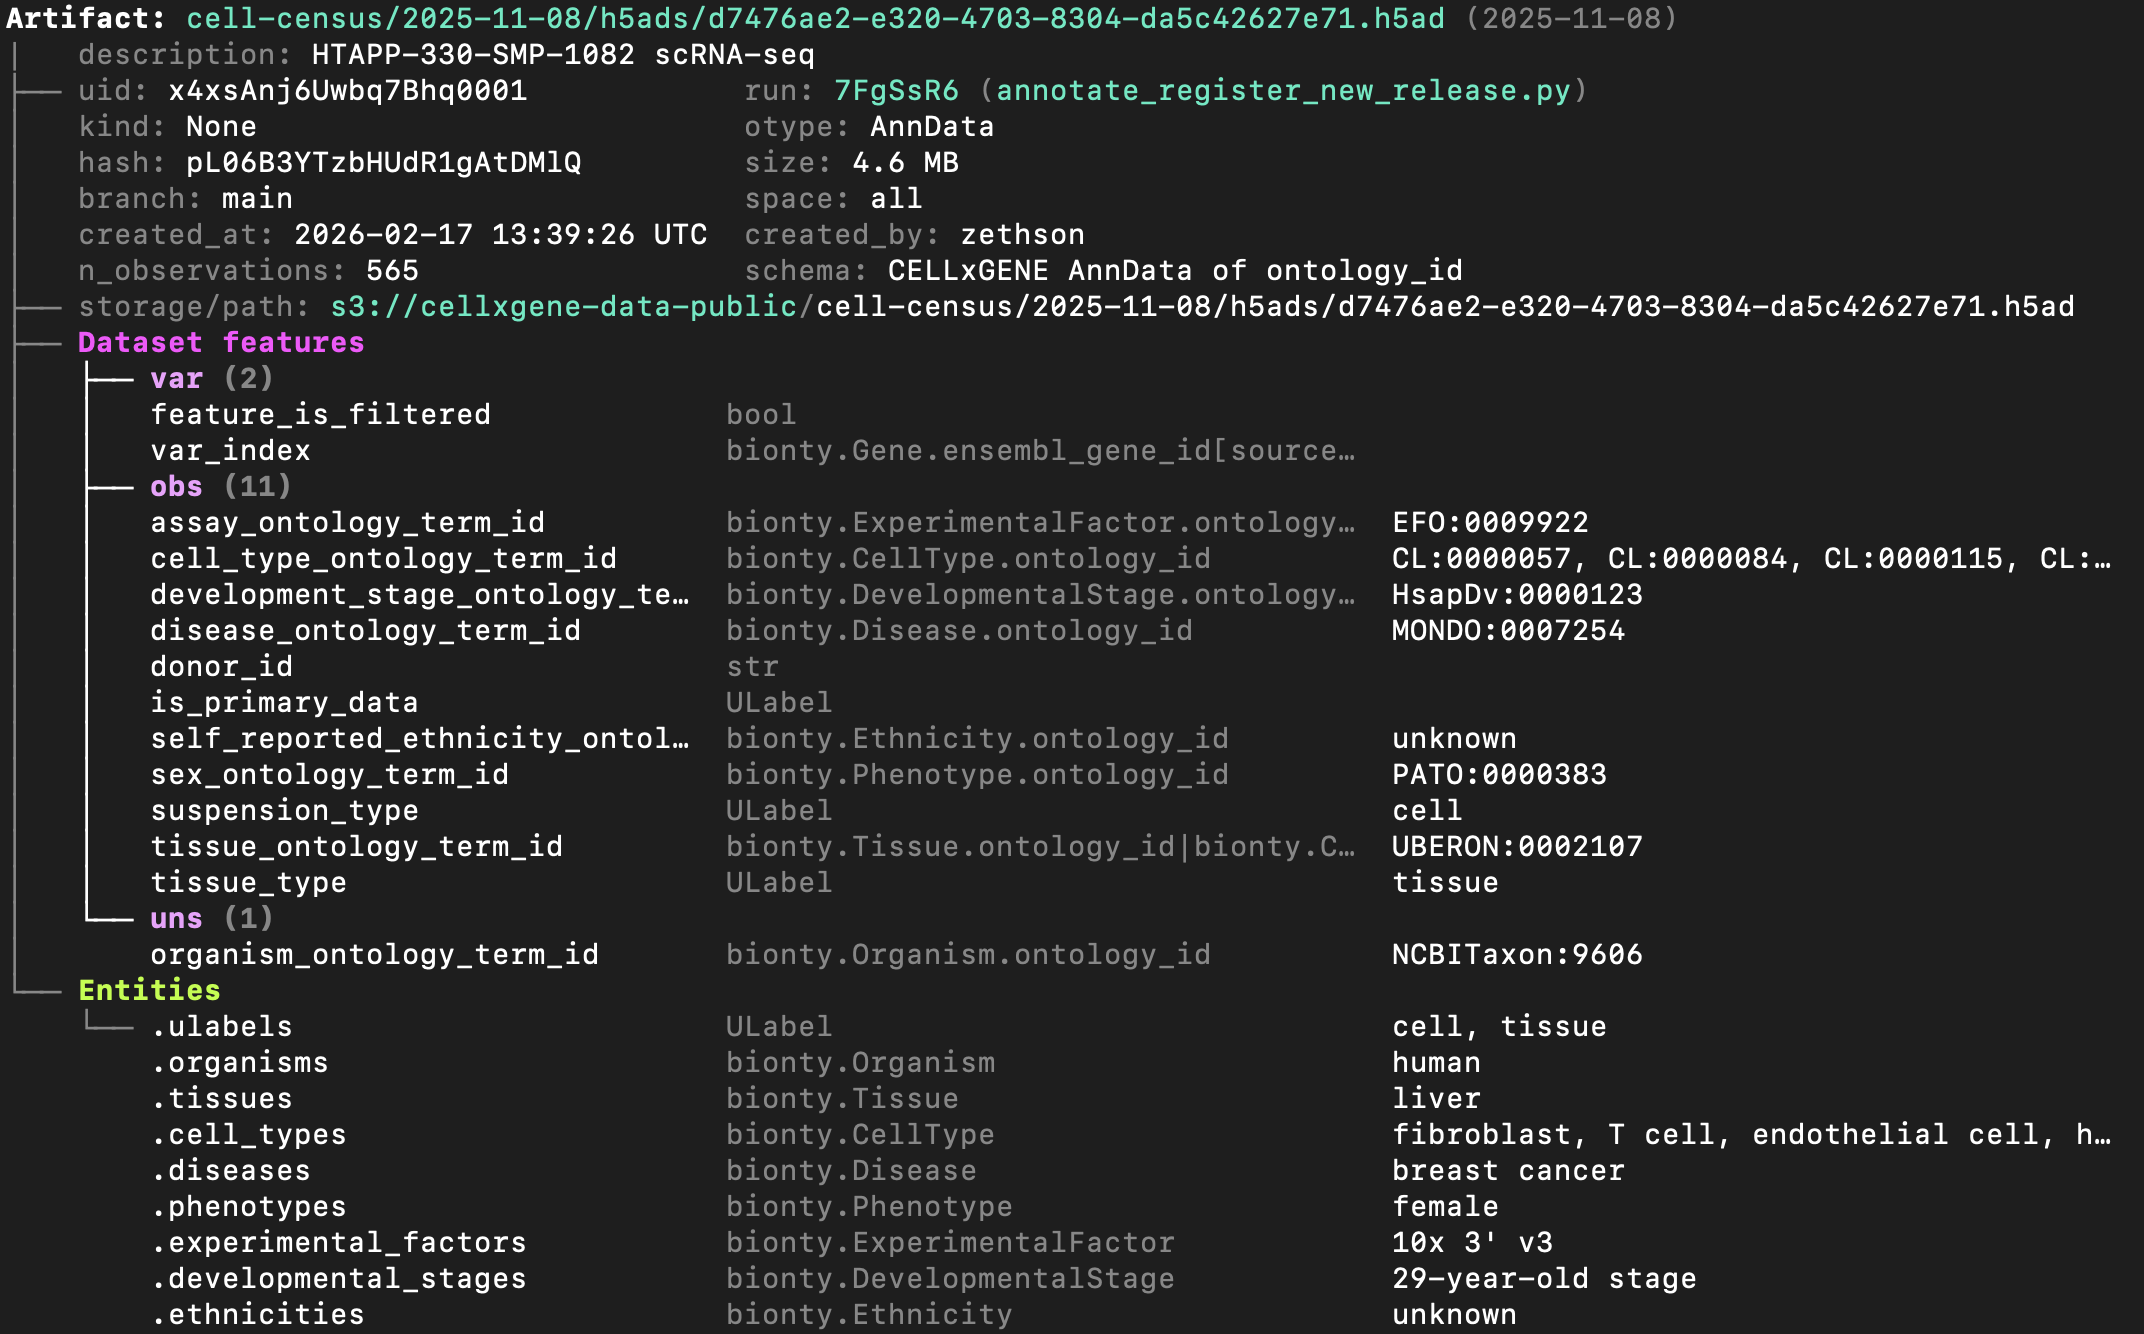
To explore the dataset on the UI, go here.
Access the content of the artifact via one of:
local_path = artifact.cache()  # return a local path from a cache
adata = artifact.load()        # load object into memory
accessor = artifact.open()     # return a streaming accessor
local_path <- artifact$cache()  # return a local path from a cache
adata <- artifact$load()        # load object into memory
accessor <- artifact$open()     # return a streaming accessor
Query a set of artifacts by entities using Django’s __ syntax:
db.Artifact.filter(tissues__name="liver").to_dataframe()
db$Artifact$filter(tissues__name = "liver")$to_dataframe()
Query by features using expressions:
tissue_feature = db.Feature.get(name="tissue_ontology_term_id")
db.Artifact.filter(
    tissue_feature == db.bionty.Tissue.get(name="liver")
).to_dataframe()
tissue_feature <- db$Feature$get(name = "tissue_ontology_term_id")
db$Artifact$filter(
    tissue_feature == db$bionty$Tissue$get(name = "liver")
)$to_dataframe()
Access sharded datasets
Access a validated, versioned collection of artifact shards in parquet format:
db = ln.DB("laminlabs/1000genomes")
collection = db.Collection.get("hVu9puwdRGskm1I6")
collection.schema.describe()
db <- ln$DB("laminlabs/1000genomes")
collection <- db$Collection$get("hVu9puwdRGskm1I6")
collection$schema$describe()
Ad-hoc query a sharded dataset.
See the validating schema of the collection (explore):
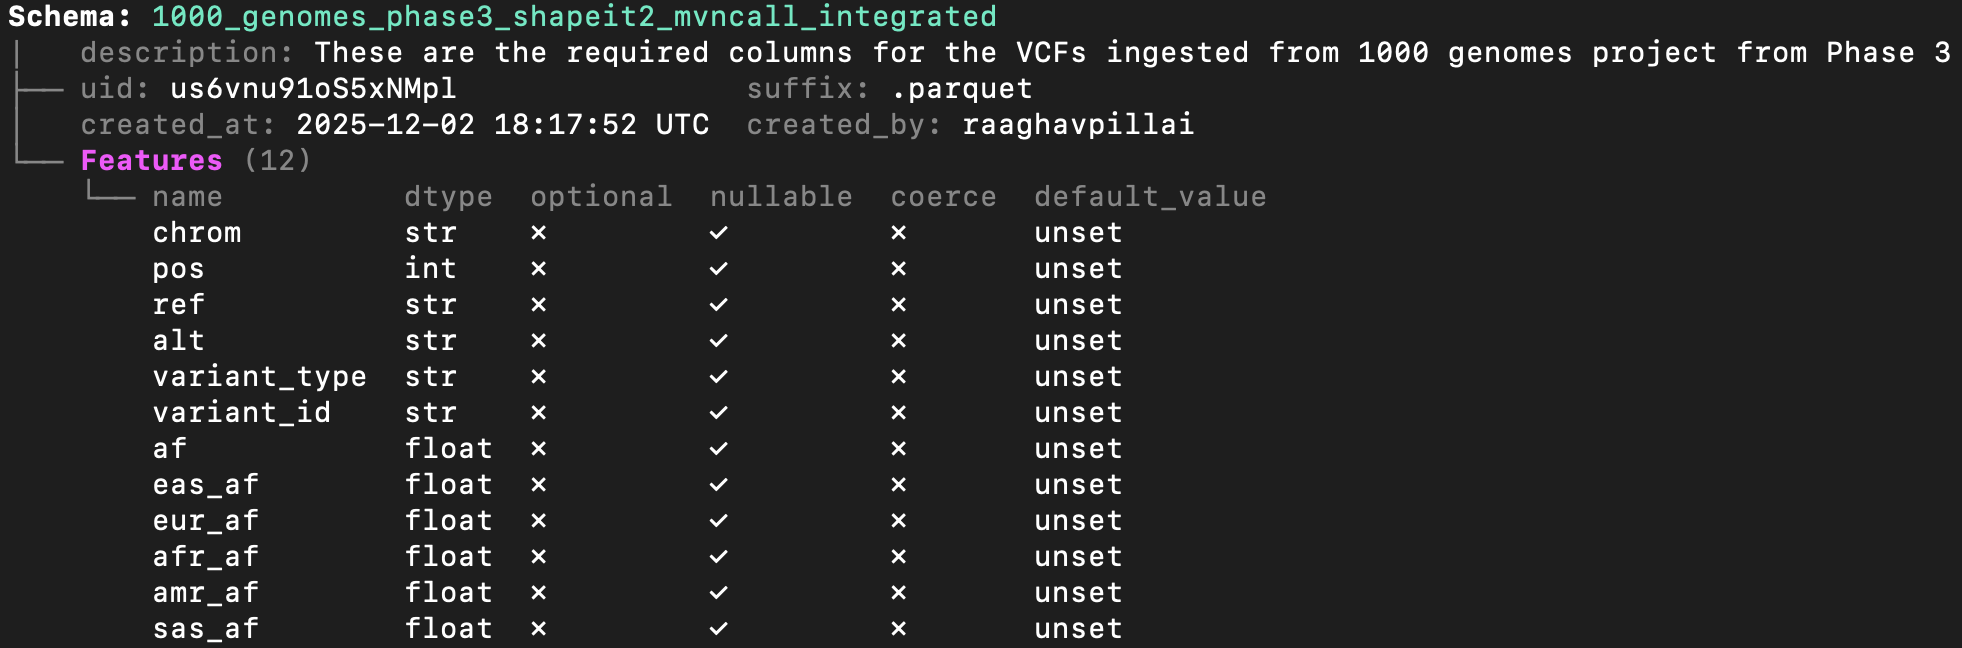
This example uses polars to filter the collection of parquet files:
chrom = "1"
lo, hi = 150_000_000, 200_000_000

with collection.open(engine="polars") as df:
    filtered = df.filter(
        (pl.col("chrom") == chrom) & (pl.col("pos") >= lo) & (pl.col("pos") <= hi)
    ).collect()
Access a collection of artifact shards in zarr format:
db = ln.DB("laminlabs/arrayloader-benchmarks")
collection = db.Collection.get(key="Tahoe100M_zarr")
collection.artifacts.to_dataframe()
db <- ln$DB("laminlabs/arrayloader-benchmarks")
collection <- db$Collection$get(key = "Tahoe100M_zarr")
collection$artifacts$to_dataframe()
Train a model on a sharded dataset.
This example uses annbatch with the pre-shuffled sharded Tahoe100M_zarr collection (explore):
import anndata as ad
import zarr
from annbatch import Loader

paths = [artifact.cache() for artifact in collection.artifacts.all()]
loader = Loader(shuffle=True, batch_size=4096, chunk_size=256, preload_nchunks=64)
loader.add_datasets(
    datasets=[ad.io.sparse_dataset(zarr.open(p)["X"]) for p in paths],
    obs=[ad.io.read_elem(zarr.open(p)["obs"]) for p in paths],
)
for batch in loader:
    pass
Create artifacts
To initialize a new database in a development directory, run:
lamin init --modules bionty # mount module bionty
To connect to an existing database - you can create a hosted one at lamin.ai - run:
lamin login
lamin connect account/name  # tip: add flag `--here` to scope to current directory
To save a file or folder:
import lamindb as ln
# → connected lamindb: account/instance

open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
library(laminr)
ln <- import_module("lamindb")
# → connected lamindb: account/instance

writeLines(">seq1\nACGT\n", "sample.fasta")        # create dataset
ln$Artifact("sample.fasta", key = "sample.fasta")$save()  # save dataset
Or via the CLI:
lamin save sample.fasta --key sample.fasta
Load it.
To load an artifact via the CLI into a local cache, run:
lamin load --key sample.fasta
Read more about the CLI: docs.lamin.ai/cli.
Trace data, code & agents
To track an agent session, run: uvx library-skills --skill lamindb.
To track a script or notebook run with source code, inputs, outputs, logs, and environment:
import lamindb as ln
# → connected lamindb: account/instance

ln.track()                                              # track code execution
open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
ln.finish()                                             # mark run as finished
library(laminr)
ln <- import_module("lamindb")
# → connected lamindb: account/instance

ln$track()                                              # track code execution
writeLines(">seq1\nACGT\n", "sample.fasta")        # create dataset
ln$Artifact("sample.fasta", key = "sample.fasta")$save()  # save dataset
ln$finish()                                             # mark run as finished
Explore data lineage after running this snippet as a script (python create_fasta.py):
artifact = ln.Artifact.get(key="sample.fasta")  # get artifact by key
artifact.describe()      # context of the artifact
artifact.view_lineage()  # fine-grained lineage
artifact <- ln$Artifact$get(key = "sample.fasta")  # get artifact by key
artifact$describe()      # context of the artifact
artifact$view_lineage()  # fine-grained lineage
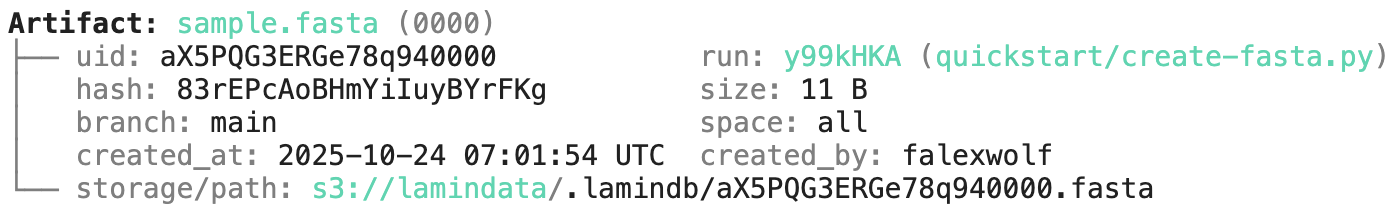
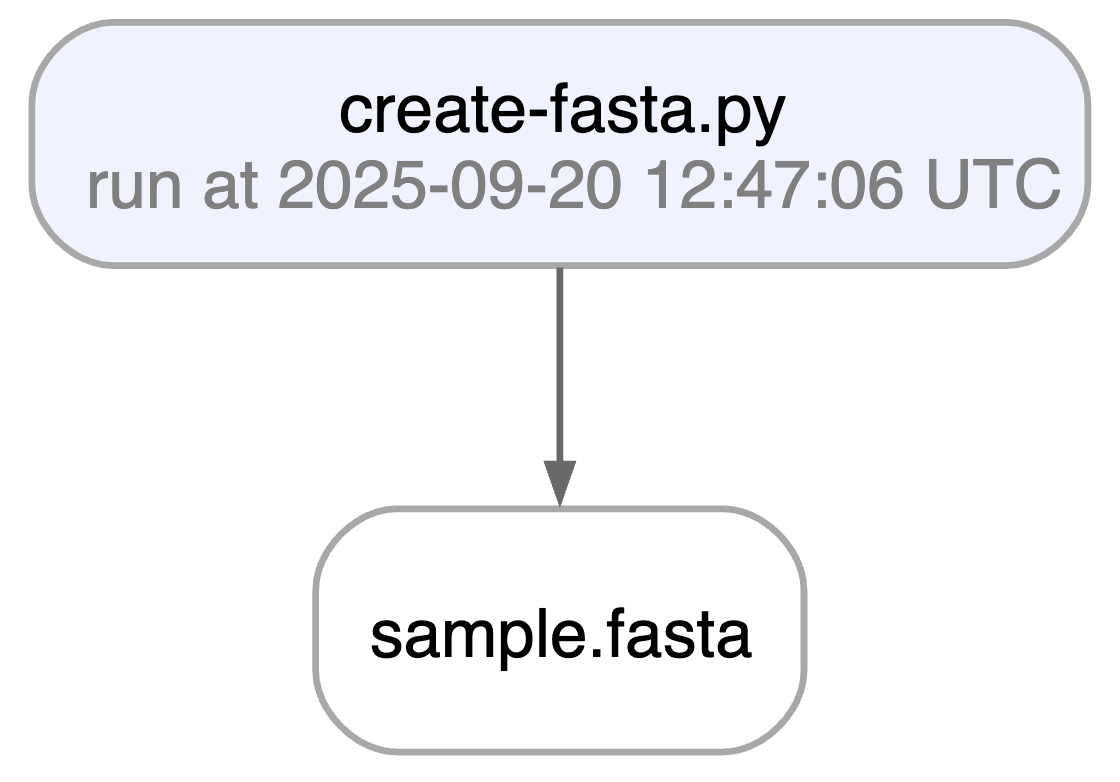
Watch a mini video: youtu.be/yK3ODFZLL1A
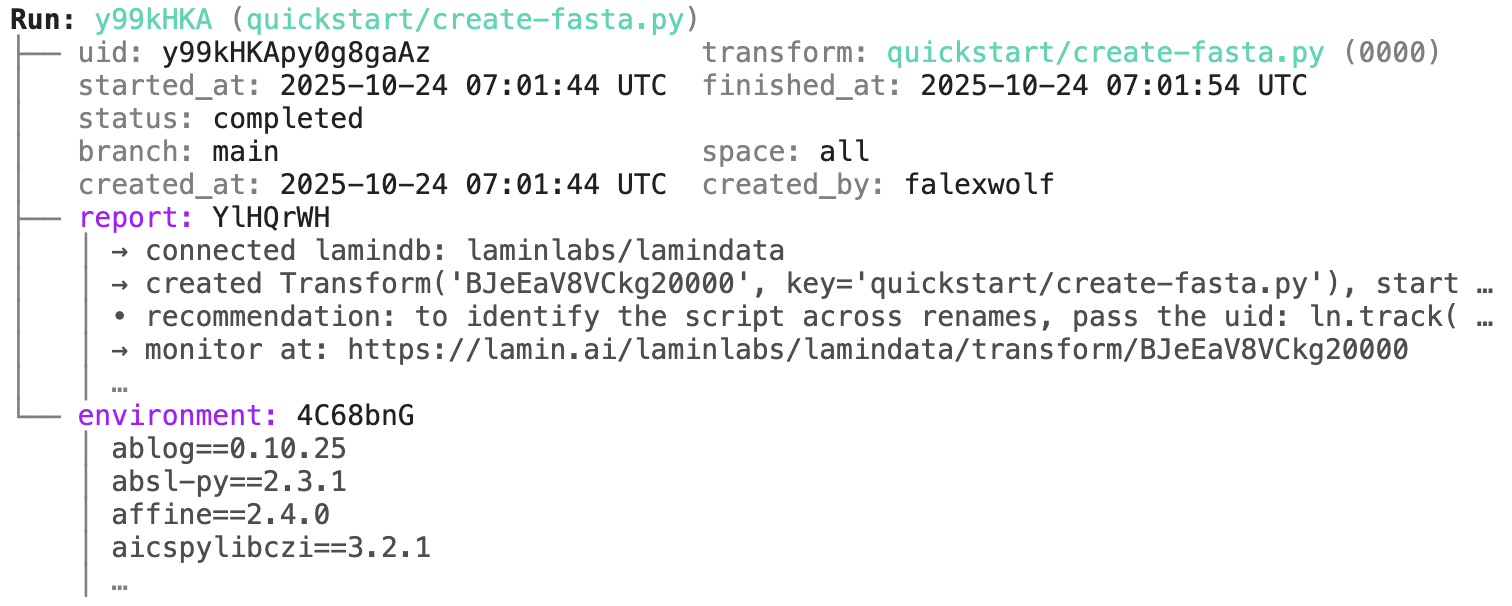
Access run & transform.
run = artifact.run                     # get the run object
transform = artifact.run.transform     # get the transform object
run.describe()                  # context of the run
run <- artifact$run                     # get the run object
transform <- artifact$run$transform     # get the transform object
run$describe()                  # context of the run
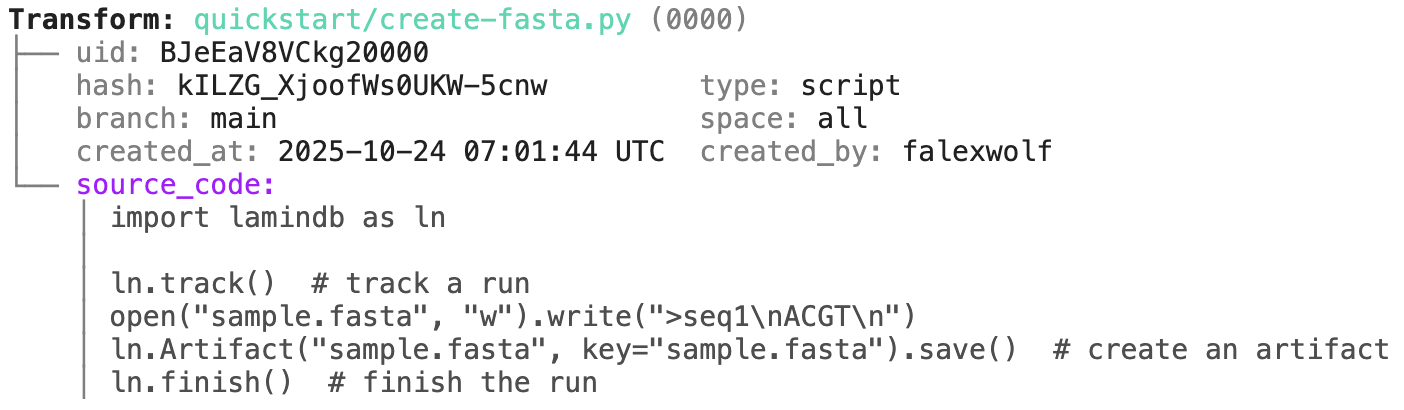
transform.describe() # context of the transform
transform$describe() # context of the transform
To track a workflow, decorate a function:
import lamindb as ln

@ln.flow()
def create_fasta(fasta_file: str = "sample.fasta"):
    open(fasta_file, "w").write(">seq1\nACGT\n")    # create dataset
    ln.Artifact(fasta_file, key=fasta_file).save()  # save dataset

if __name__ == "__main__":
    create_fasta()
Beyond what you get for scripts & notebooks, this automatically tracks function & CLI params and integrates well with established Python workflow managers: docs.lamin.ai/track. To integrate pipeline managers like Nextflow, see docs.lamin.ai/pipelines.
A richer example.
Here is a re-construction of the project of Schmidt et al. (Science, 2022):
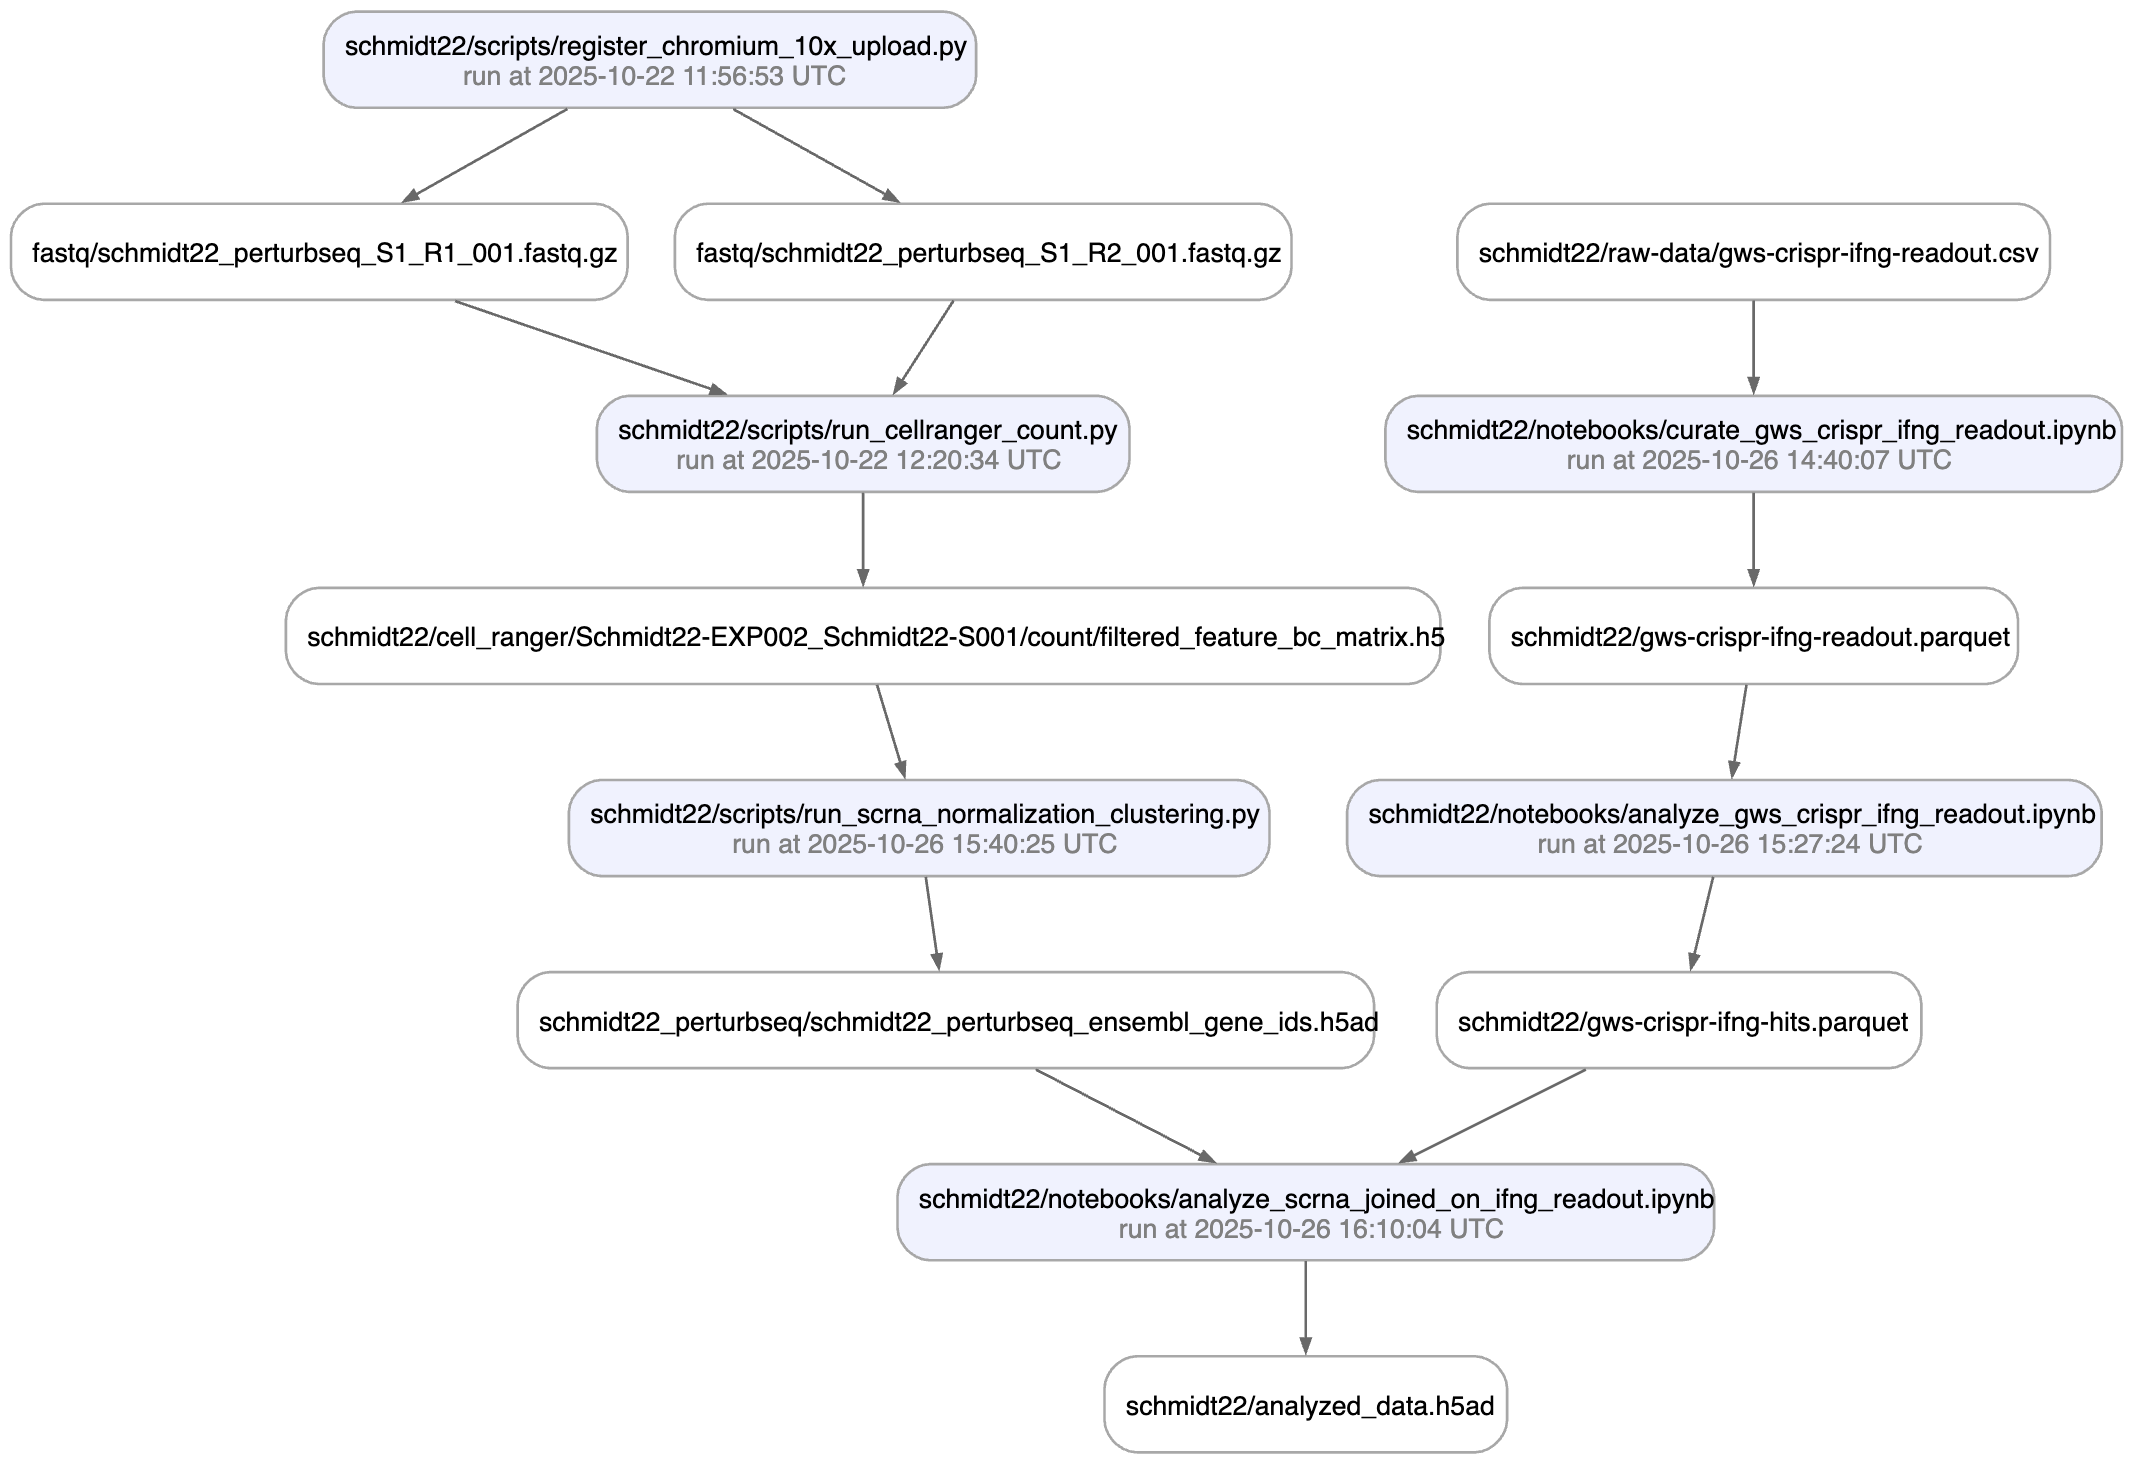
A phenotypic CRISPRa screening result is integrated with scRNA-seq data. Here is the result of the screen input:
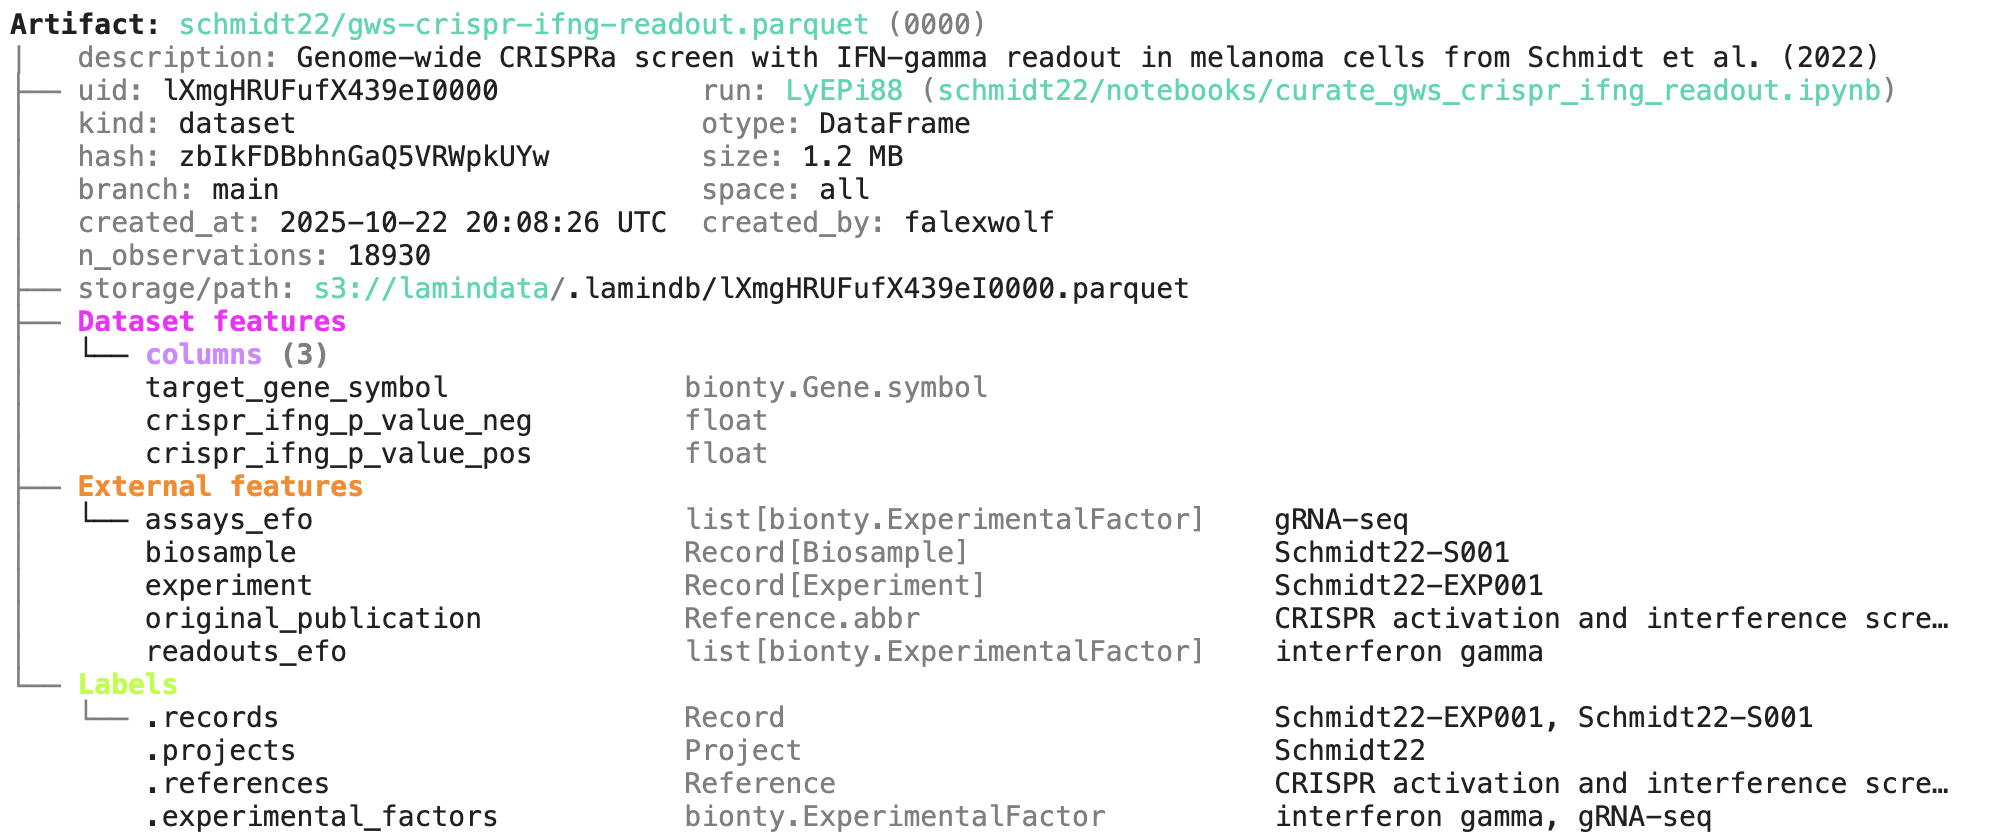
You can explore it here.
Annotate & query artifacts
To annotate and query by entities:
# create entities
my_label = ln.ULabel(name="My universal label").save()
my_project = ln.Project(name="My project label").save()

# annotate
artifact.ulabels.add(my_label)
artifact.projects.add(my_project)

# query
ln.Artifact.filter(ulabels=my_label, projects=my_project).to_dataframe()
# create entities
my_label <- ln$ULabel(name = "My universal label")$save()
my_project <- ln$Project(name = "My project label")$save()

# annotate
artifact$ulabels$add(my_label)
artifact$projects$add(my_project)

# query
ln$Artifact$filter(ulabels = my_label, projects = my_project)$to_dataframe()
This also works for entities imported from modules, for example, ontology terms:
import bionty as bt

# import an entity from a public ontology source, e.g., by name or an ontology ID
hek293 = bt.CellLine.from_source(name="HEK293").save()
hras = bt.Gene.from_source(ensembl_gene_id="ENSG00000174775").save()

# annotate
artifact.cell_lines.add(hek293)
artifact.genes.add(hras)

# query
ln.Artifact.filter(cell_lines=hek293, genes=hras).to_dataframe(
    include=["cell_lines__name", "genes__symbol"]
)
bt <- import_module("bionty")

# import an entity from a public ontology source, e$g., by name or an ontology ID
hek293 <- bt$CellLine$from_source(name = "HEK293")$save()
hras <- bt$Gene$from_source(ensembl_gene_id = "ENSG00000174775")$save()

# annotate
artifact$cell_lines$add(hek293)
artifact$genes$add(hras)

# query
ln$Artifact$filter(cell_lines = hek293, genes = hras)$to_dataframe(
    include = list("cell_lines__name", "genes__symbol")
)
To annotate & query by features:
from datetime import date

# define features
gc_content = ln.Feature(name="gc_content", dtype=float).save()
seq_date = ln.Feature(name="seq_date", dtype=date).save()

# annotate
artifact.features.set_values({
    gc_content: 0.55,
    seq_date: date.today(),
})

# query
ln.Artifact.filter(seq_date == date.today()).to_dataframe(include="features")
datetime <- import_module("datetime")
date <- datetime$date

# define features
gc_content <- ln$Feature(name = "gc_content", dtype = "float")$save()
seq_date <- ln$Feature(name = "seq_date", dtype = date)$save()

# annotate
artifact$features$set_values(list(
    gc_content = 0.55,
    seq_date = date$today()
))

# query
ln$Artifact$filter(seq_date == date$today())$to_dataframe(include = "features")
To query by auto-tracked metadata:
# by storage location and size
ln.Artifact.filter(storage__root=ln.settings.storage.root)
ln.Artifact.filter(size__gt=1e6).to_dataframe()

# by data lineage
ln.Artifact.filter(run=run).to_dataframe()
ln.Artifact.filter(run__transform=transform).to_dataframe()

# include more information in resulting dataframe
ln.Artifact.to_dataframe(include=["run__transform__key", "storage__root"])
# by storage location and size
ln$Artifact$filter(storage__root = ln$settings$storage$root)
ln$Artifact$filter(size__gt = 1e6)$to_dataframe()

# by data lineage
ln$Artifact$filter(run = run)$to_dataframe()
ln$Artifact$filter(run__transform = transform)$to_dataframe()

# include more information in resulting dataframe
ln$Artifact$to_dataframe(include = list("run__transform__key", "storage__root"))
Read more: docs.lamin.ai/organize or docs.lamin.ai/query-search
Create records & notes
You can create record types to model metadata for any entity:
# create record types
experiment_type = ln.Record(name="Experiments", is_type=True).save()
sample_type = ln.Record(name="Samples", is_type=True).save()

# create an experiment
experiment1 = ln.Record(
    name="Experiment 1",
    features={seq_date: date.today()},
    type=experiment_type
).save()

# create a sample that links to "Experiment 1" via a feature
experiment = ln.Feature(name="experiment", dtype=experiment_type).save()
sample1 = ln.Record(
    features={gc_content: 0.5, experiment: experiment1},
    type=sample_type
).save()

# export all experiments and all samples
experiment_type.to_dataframe()
sample_type.to_dataframe()
# create record types
experiment_type <- ln$Record(name = "Experiments", is_type = TRUE)$save()
sample_type <- ln$Record(name = "Samples", is_type = TRUE)$save()

# create an experiment
experiment1 <- ln$Record(
    name = "Experiment 1",
    features = list(seq_date = date$today()),
    type = experiment_type
)$save()

# create a sample that links to "Experiment 1" via a feature
experiment <- ln$Feature(name = "experiment", dtype = experiment_type)$save()
sample1 <- ln$Record(
    features = list(gc_content = 0.5, experiment = experiment1),
    type = sample_type
)$save()

# export all experiments and all samples
experiment_type$to_dataframe()
sample_type$to_dataframe()
You can save markdown notes as records:
lamin save <topic>/<my-note.md>
Load it.
To load a record back as a markdown file, run:
lamin load https://lamin.ai/laminlabs/lamindata/record/mNDJgWFrkWQVW3ox
Watch a mini video: youtu.be/NRzVQXJaRH8
Read more: docs.lamin.ai/manage-records.
Validate datasets
Here is how you ingest a DataFrame:
import pandas as pd

df = pd.DataFrame({
    "seq_str": ["ACGT", "TGCA"],
    "gc_content": [0.55, 0.54],
    "experiment_note": ["Looks great", "Ok"],
    "seq_date": [date(2025, 10, 24), date(2025, 10, 25)],
})
ln.Artifact.from_dataframe(df, key="my_datasets/sequences.parquet").save()  # no validation
pd <- import_module("pandas")

df <- pd$DataFrame(list(
    seq_str = list("ACGT", "TGCA"),
    gc_content = list(0.55, 0.54),
    experiment_note = list("Looks great", "Ok"),
    seq_date = list(date(2025L, 10L, 24L), date(2025L, 10L, 25L))
))
ln$Artifact$from_dataframe(df, key = "my_datasets/sequences.parquet")$save()  # no validation
The simplest way to validate & annotate the content of the dataframe is the built-in schema valid_features:
ln.Feature(name="seq_str", dtype=str).save()  # define remaining features
ln.Feature(name="experiment_note", dtype=str).save()
artifact = ln.Artifact.from_dataframe(
    df,
    key="my_datasets/sequences.parquet",
    schema="valid_features"  # validate columns against features
).save()
artifact.describe()
ln$Feature(name = "seq_str", dtype = "str")$save()  # define remaining features
ln$Feature(name = "experiment_note", dtype = "str")$save()
artifact <- ln$Artifact$from_dataframe(
    df,
    key = "my_datasets/sequences.parquet",
    schema = "valid_features"  # validate columns against features
)$save()
artifact$describe()
You can filter for datasets by schema and then launch distributed queries or batch load distributed datasets. For tables, see: docs.lamin.ai/tables. For arrays, see: docs.lamin.ai/arrays.
Watch a mini video: youtu.be/Ji6E7hTnReQ
To validate an AnnData, call:
import anndata as ad
import numpy as np
import pandas as pd

adata = ad.AnnData(
    X=np.ones((21, 10)),
    obs=pd.DataFrame({'cell_type_by_model': ['T cell', 'B cell', 'NK cell'] * 7}),
    var=pd.DataFrame(index=[f'ENSG{i:011d}' for i in range(10)])
)
artifact = ln.Artifact.from_anndata(
    adata,
    key="my_datasets/scrna.h5ad",
    schema="ensembl_gene_ids_and_valid_features_in_obs"
).save()
artifact.describe()
ad <- import_module("anndata")
np <- import_module("numpy")
pd <- import_module("pandas")

adata <- anndata::AnnData(
    X = np$ones((21, 10)),
    obs = pd$DataFrame(list(cell_type_by_model = rep(list('T cell', 'B cell', 'NK cell'), 7))),
    var = pd$DataFrame(index = sprintf("ENSG%010d", 1:10))
)
artifact <- ln$Artifact$from_anndata(
    adata,
    key = "my_datasets/scrna.h5ad",
    schema = "ensembl_gene_ids_and_valid_features_in_obs"
)$save()
artifact$describe()
To validate a SpatialData or any other array-like dataset, you need to construct a Schema. You can do this by composing simple pandera-style schemas: docs.lamin.ai/curate.
Use branching & versioning
LaminDB versions transforms, artifacts, and collections.
If you edit and run the create_fasta.py script, you’ll automatically create a new version of the transform and the sample.fasta artifact.
The edited script.
# create_fasta.py
import lamindb as ln

ln.track()
open("sample.fasta", "w").write(">seq1\nTGCA\n")  # a new sequence
ln.Artifact("sample.fasta", key="sample.fasta", features={"experiment": "Experiment 1"}).save()  # annotate with the new experiment
ln.finish()
# create_fasta$py
library(laminr)
ln <- import_module("lamindb")

ln$track()
writeLines(">seq1\nTGCA\n", "sample.fasta")  # a new sequence
ln$Artifact("sample.fasta", key = "sample.fasta", features = list(experiment = "Experiment 1"))$save()  # annotate with the new experiment
ln$finish()
artifact_latest = ln.Artifact.get(key="sample.fasta")  # pass version for a previous version: ln.Artifact.get(key="sample.fasta", version="1.0")
artifact_latest.versions.to_dataframe()                # all versions of that artifact
artifact_latest.run.transform.versions.to_dataframe()  # all versions of the transform that created the artifact
artifact_latest <- ln$Artifact$get(key = "sample.fasta")  # pass version for a previous version: ln$Artifact$get(key = "sample.fasta", version = "1.0")
artifact_latest$versions$to_dataframe()                # all versions of that artifact
artifact_latest$run$transform$versions$to_dataframe()  # all versions of the transform that created the artifact
If you create a branch and switch to it as in git, you’ll create new objects and new versions of objects on it:
lamin switch -c my_branch
To merge a contribution branch into main, run:
lamin switch main  # switch to the main branch
lamin merge my_branch  # merge contribution branch into main
Read more: docs.lamin.ai/manage-changes.
Watch a mini video: youtu.be/rzRwcMj6-fc
Manage ontologies
You can use Record to build your ELN & LIMS, your own ontologies, and even a knowledge graph with slow graph queries. If you instead want to build on public biological ontologies: bionty gives you >20 public ontologies so that you don’t have build ontologies for basic biological entities from scratch. For example, the Gene registry was used to validate the ENSG ids in the AnnData object above.
Here is how you import a public ontology into the CellType registry:
import bionty as bt

bt.CellType.import_source()  # import the default ontology
bt.CellType.to_dataframe()   # your extensible cell type ontology in a simple registry
bt <- import_module("bionty")

bt$CellType$import_source()  # import the default ontology
bt$CellType$to_dataframe()   # your extensible cell type ontology in a simple registry
You can then create objects, e.g. for labeling, analogous to ULabel or Project:
t_cell = bt.CellType.get(name="T cell")  # get a T cell label
artifact.cell_types.add(t_cell)          # annotate an artifact
t_cell <- bt$CellType$get(name = "T cell")  # get a T cell label
artifact$cell_types$add(t_cell)          # annotate an artifact
Read more: docs.lamin.ai/manage-ontologies.
Watch a mini video: youtu.be/3vpWjHj3Kw8