Track notebooks, scripts & workflows 
 
This guide walks from tracking data lineage in a notebook to tracking parameters in workflows.
To run examples, if you don’t have a lamindb instance, create one:
lamin init
Show code cell output
→ dev-dir is: /home/runner/work/lamindb/lamindb/docs
→ initialized lamindb: testuser1/docs
Track agent runs
Sessions
The lamindb skill ships with the lamindb package at .agents/skills/. Ask your coding agent to copy it to wherever it reads skills from — .claude/skills/ for Claude Code, .agents/skills/ for GitHub Copilot — so that it automatically tracks agent sessions.
When the agent finishes a session with lamin finish, usage metrics are recorded in run.extra_data:
n_tokens: total tokens for the sessionn_steps: number of LLM completions/turnsn_tool_calls: number of tool invocations
Details
For Claude Code, n_tokens is the full billed total (input + output + cache-read + cache-write tokens), matching how Anthropic and tools like ccusage compute session cost.
For GitHub Copilot, n_tokens presently is an output-tokens-only lower bound, not a full billed total. Don’t compare n_tokens across the two agents directly.
Plans
You can save an agent plan like this:
lamin save /path/to/.cursor/plans/my_task.plan.md
lamin save /path/to/.claude/plans/my_task.md
Track scripts and notebooks
Call track() to save your notebook or script as a transform and start tracking inputs & outputs of a run.
import lamindb as ln

ln.track()  # initiate a tracked notebook/script run

# your code automatically tracks inputs & outputs

ln.finish()  # mark run as finished, save execution report, source code & environment
You find your notebooks and scripts in the Transform registry along with pipelines & functions:
transform = ln.Transform.get(key="my_analyses/my_notebook.ipynb")
transform.source_code             # source code
transform.runs.to_dataframe()     # all runs in a dataframe
transform.latest_run.report       # report of latest run
transform.latest_run.environment  # environment of latest run
You can use the CLI to load a transform into your current (development) directory:
lamin load --key my_analyses/my_notebook.ipynb
Here is how you’d load the notebook from the video into your local directory:
lamin load https://lamin.ai/laminlabs/lamindata/transform/F4L3oC6QsZvQ
Use projects
You can link the entities created during a run to a project.
import lamindb as ln

my_project = ln.Project(name="My project").save()  # create & save a project
ln.track(project="My project")  # pass project
open("sample.fasta", "w").write(">seq1\nACGT\n")  # create a dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # auto-labeled by project
Show code cell output
→ connected lamindb: testuser1/docs
! tip: pass `type` to map project into a type hierarchy
→ created Transform('scDZ6zghkXU50000', key='track.ipynb'), started new Run('mDiJLMgSJrRXJXUb') at 2026-09-15 07:25:11 UTC
→ notebook imports: lamindb
• tip: to identify the notebook across renames, pass the uid: ln.track("scDZ6zghkXU5", project="My project")
Artifact(uid='XLZaL6raaKYTTuD40000', key='sample.fasta', description=None, suffix='.fasta', kind=None, otype=None, size=11, hash='83rEPcAoBHmYiIuyBYrFKg', n_files=None, n_observations=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=1, schema_id=None, created_by_id=1, created_at=2026-09-15 07:25:14 UTC, is_locked=False, version_tag=None, is_latest=True)
Filter entities by project, e.g., artifacts:
ln.Artifact.filter(projects=my_project).to_dataframe()
Show code cell output
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 1 | XLZaL6raaKYTTuD40000 | sample.fasta | None | .fasta | None | None | 11 | 83rEPcAoBHmYiIuyBYrFKg | None | None | ... | True | False | 2026-09-15 07:25:14.894000+00:00 | 1 | 1 | 1 | 1 | 1 | None | 1 |
1 rows × 22 columns
Access entities linked to a project:
my_project.artifacts.to_dataframe()
Show code cell output
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 1 | XLZaL6raaKYTTuD40000 | sample.fasta | None | .fasta | None | None | 11 | 83rEPcAoBHmYiIuyBYrFKg | None | None | ... | True | False | 2026-09-15 07:25:14.894000+00:00 | 1 | 1 | 1 | 1 | 1 | None | 1 |
1 rows × 22 columns
The same works for my_project.transforms or my_project.runs.
Use spaces
You can write the entities created during a run into a space that you configure on LaminHub. This is particularly useful if you want to restrict access to a space. Note that this doesn’t affect bionty entities who should typically be commonly accessible.
ln.track(space="Our team space")
Organize local development
Development directory
The development directory (dev-dir) is the local root LaminDB uses to map script, notebook, and notes paths.
If a development directory is set, keys are stored as paths relative to that directory.
Packaged source code uses
pypackages/{package_name}/path/to/file.py.
Whenever you’re not just reading from but writing to a LaminDB instance, configure a development directory already during connection by passing the --here flag:
lamin connect --here account/name
You can also configure the development directory independent from connecting by running:
lamin settings set dev-dir .
You can see the current configuration by running:
lamin info
When you cd into the development directory, LaminDB auto-connects to the configured database.
Worktree
If you enable worktree mode, LaminDB interprets dev-dir as a parent directory that contains one child directory per branch, inspired by git worktree.
lamin settings set worktree true
In this mode, each child directory maps on a branch, which is useful if multiple agents work in parallel on different branches in the same environment. Typical flow:
lamin switch -c branch-a
cd branch-a
Here is an examplary structure:
dbs/
  my_instance/                # development directory (dev-dir)
    .lamin/
    branch-a/                 # branch directory in the worktree
      analysis/
        script1.py
    branch-b/                 # another branch directory with another version of script1.py
      analysis/
        script1.py
Sync code with git
To sync scripts or workflow definitions with their correponding files in a git repo, either export an environment variable:
export LAMINDB_SYNC_GIT_REPO = <YOUR-GIT-REPO-URL>
Or set the following setting:
ln.settings.sync_git_repo = <YOUR-GIT-REPO-URL>
If you work on a single project in your lamindb instance, it makes sense to set LaminDB’s dev-dir to the root of the local git repo clone.
dbs/
  project1/
    .git/
    .lamin/
    script1.py
    notebook1.ipynb
  ...
If you work on multiple projects in your lamindb instance, you can use the dev-dir as the local root and nest git repositories in it.
dbs/
  database1/
    .lamin/
    repo1/
      .git/
    repo2/
      .git/
  ...
Manage workflows
Here we’ll manage workflows with lamindb’s flow() and step() decorators, which works out-of-the-box with the majority of Python workflow managers:
tool |
workflow decorator |
step/task decorator |
notes |
|---|---|---|---|
|
|
|
inspired by |
|
|
|
two decorators |
|
|
|
single decorator for everything |
|
|
|
asset-centric; |
|
|
|
also |
|
|
|
TaskFlow API (modern); also supports operators |
|
|
|
inspired by |
If you’re looking for more in-depth examples or for integrating with non-decorator-based workflow managers such as Nextflow or Snakemake, see Manage computational pipelines.
tool |
workflow |
step/task |
notes |
|---|---|---|---|
|
|
|
groovy-based DSL |
|
|
|
file-based DSL |
|
|
|
class-based |
|
|
|
function-based |
A one-step workflow
Decorate a function with flow() to track it as a workflow:
import lamindb as ln


@ln.flow()
def ingest_dataset(key: str) -> ln.Artifact:
    df = ln.examples.datasets.mini_immuno.get_dataset1()
    artifact = ln.Artifact.from_dataframe(df, key=key).save()
    return artifact


if __name__ == "__main__":
    ingest_dataset(key="my_analysis/dataset.parquet")
Let’s run the workflow:
python scripts/my_workflow.py
Show code cell output
→ connected lamindb: testuser1/docs
→ created Transform('kuHcUQ5HnEdn0000', key='scripts/my_workflow.py'), started new Run('a
GPS3pADFqlpr6AI', entrypoint='ingest_dataset') at 2026-09-15 07:25:17 UTC
→ params: key='my_analys
is/dataset.parquet'
• tip: to identify the script across renames, pass the uid: @ln.flow(uid="kuHcUQ5HnEdn")
Query the workflow via its filename:
transform = ln.Transform.get(key__endswith="my_workflow.py")
transform.describe()
Show code cell output
Transform: scripts/my_workflow.py (0000)
├── uid: kuHcUQ5HnEdn0000
│   hash: uJ3fsnfaNN6EZ7Q0d8SQtw         type: script
│   branch: main                         space: all
│   created_at: 2026-09-15 07:25:17 UTC  created_by: testuser1
└── source_code:
    │ import lamindb as ln
    │
    │
    │ @ln.flow()
    │ def ingest_dataset(key: str) -> ln.Artifact:
    │     df = ln.examples.datasets.mini_immuno.get_dataset1()
    │     artifact = ln.Artifact.from_dataframe(df, key=key).save()
    │     return artifact
    │
    │
    │ if __name__ == "__main__":
    │     ingest_dataset(key="my_analysis/dataset.parquet")
The run stored the parameter value for key:
transform.latest_run.describe()
Show code cell output
Run: aGPS3pA (scripts/my_workflow.py)
├── uid: aGPS3pADFqlpr6AI                transform: scripts/my_workflow.py (0000)
│   started_at: 2026-09-15 07:25:18 UTC  finished_at: 2026-09-15 07:25:23 UTC
│   status: completed
│   branch: main                         space: all
│   created_at: 2026-09-15 07:25:18 UTC  created_by: testuser1
├── report: Jk5n5BQ
│   │ → connected lamindb: testuser1/docs
│   │ → created Transform('kuHcUQ5HnEdn0000', key='scripts/my_workflow.py'), started n …
│   │ → params: key='my_analysis/dataset.parquet'
│   │ • tip: to identify the script across renames, pass the uid: @ln.flow(uid="kuHcUQ …
├── environment: GHGsyn7
│   │ aiobotocore==3.9.1
│   │ aiohappyeyeballs==2.7.1
│   │ aiohttp==3.14.3
│   │ aioitertools==0.13.0
│   │ …
└── Params
    └── key: my_analysis/dataset.parquet
It links output artifacts:
transform.latest_run.output_artifacts.to_dataframe()
Show code cell output
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 3 | Ltugp64VksWVApsK0000 | my_analysis/dataset.parquet | None | .parquet | dataset | DataFrame | 10315 | 9VU_toJu0mQ3tqdMjHyUkg | None | 3 | ... | True | False | 2026-09-15 07:25:23.300000+00:00 | 1 | 1 | 1 | 1 | 2 | None | 1 |
1 rows × 22 columns
You can query for all runs that ran with that parameter:
ln.Run.filter(
    params__key="my_analysis/dataset.parquet",
).to_dataframe()
Show code cell output
| uid | name | description | entrypoint | started_at | finished_at | params | extra_data | reference | reference_type | ... | created_at | branch_id | created_on_id | space_id | transform_id | report_id | environment_id | plan_id | created_by_id | initiated_by_run_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 2 | aGPS3pADFqlpr6AI | None | None | ingest_dataset | 2026-09-15 07:25:18.427000+00:00 | 2026-09-15 07:25:23.306099+00:00 | {'key': 'my_analysis/dataset.parquet'} | None | None | None | ... | 2026-09-15 07:25:18.427000+00:00 | 1 | 1 | 1 | 2 | 4 | 2 | None | 1 | None |
1 rows × 22 columns
Validate parameters with type annotations
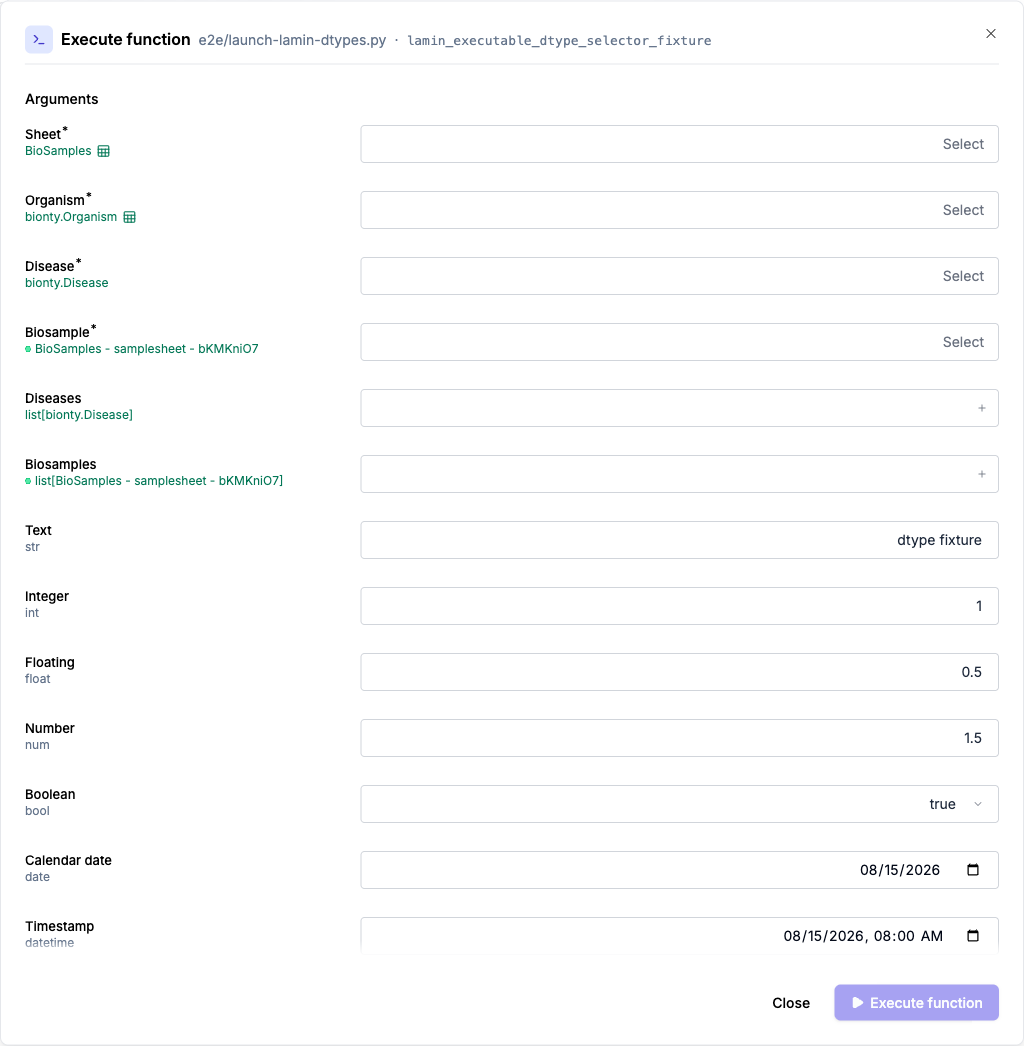
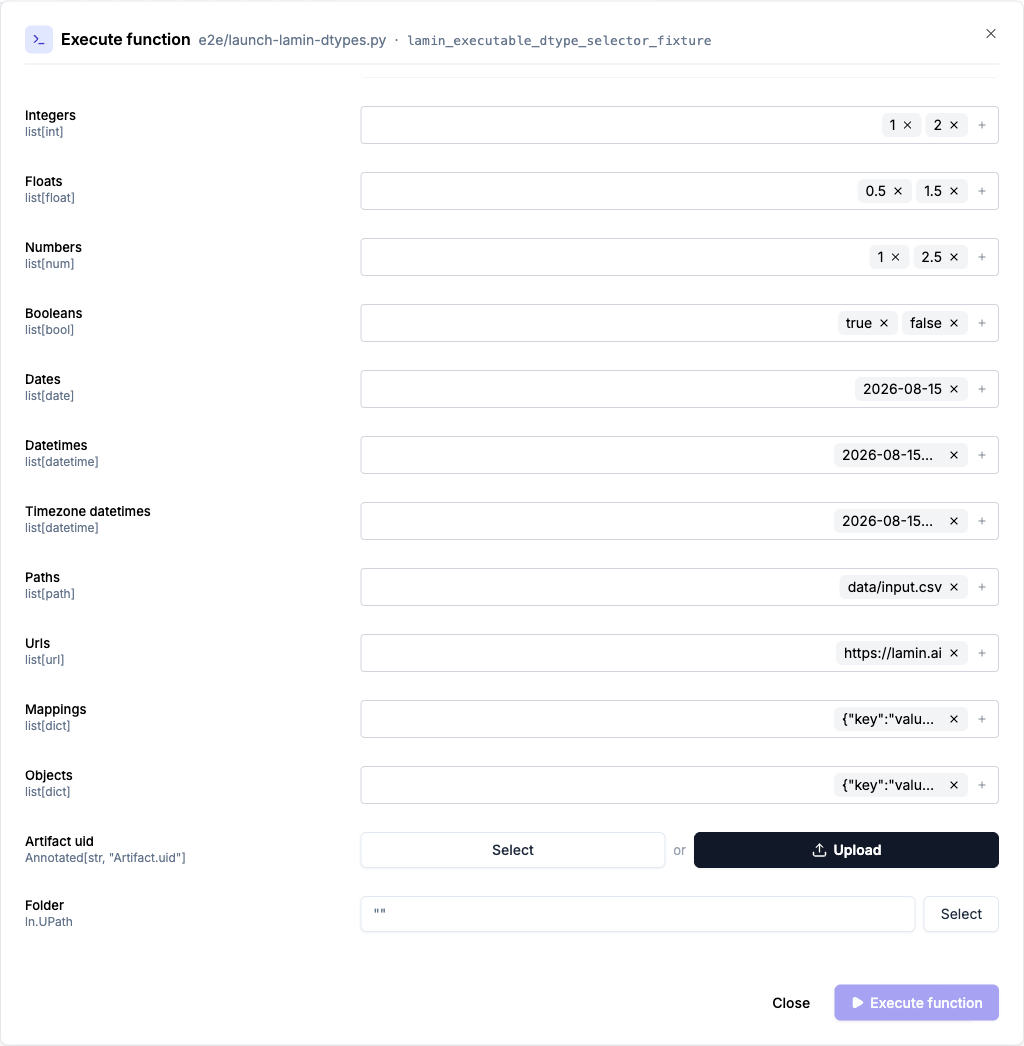
If a function is type-annotated, parameters will be validated. You can use standard Python types for simple data and valid LaminDB dtype serializations to reference objects in registries. See dtypes for more background.
@ln.flow()
def my_func(
    learning_rate: float,
    run_name: str,
    started_at: datetime,
    organism: "cat[bionty.Organism[source__uid=4eeXrDKBKo]]",
    sheet: "cat[Record[YSS8VU4eeXrDKBKo, is_type=True, schema__uid=6pjoBrrz4f1EzQMO]]",
    diseases: "list[cat[bionty.Disease[source__uid=4a3ejKuf]]]",
    gene_id: "cat[bionty.Gene.ensembl_gene_id[source__uid=6w75X9zM]]",
) -> str:
    ...
You can launch type-annotated functions through the UI.
A multi-step workflow
Here, the workflow calls an additional processing step:
import lamindb as ln


@ln.step()
def subset_dataframe(
    artifact: ln.Artifact,
    subset_rows: int = 2,
    subset_cols: int = 2,
) -> ln.Artifact:
    df = artifact.load()
    new_data = df.iloc[:subset_rows, :subset_cols]
    new_key = artifact.key.replace(".parquet", "_subsetted.parquet")
    return ln.Artifact.from_dataframe(new_data, key=new_key).save()


@ln.flow()
def ingest_dataset(key: str, subset: bool = False) -> ln.Artifact:
    df = ln.examples.datasets.mini_immuno.get_dataset1()
    artifact = ln.Artifact.from_dataframe(df, key=key).save()
    if subset:
        artifact = subset_dataframe(artifact)
    return artifact


if __name__ == "__main__":
    ingest_dataset(key="my_analysis/dataset.parquet", subset=True)
Let’s run the workflow:
python scripts/my_workflow_with_step.py
Show code cell output
→ connected lamindb: testuser1/docs
→ created Transform('Kf6ezGuQyCmq0000', key='scripts/my_workflow_with_step.py'), started
new Run('2rSxYvcl04XTGgXK', entrypoint='ingest_dataset') at 2026-09-15 07:25:25 UTC
→ params: key=
'my_analysis/dataset.parquet', subset=True
• tip: to identify the script across renames, pass the uid: @ln.flow(uid="Kf6ezGuQyCmq")
→ returning artifact with same hash: Artifact(uid='Ltugp64VksWVApsK0000', key='my_analysi
s/dataset.parquet', description=None, suffix='.parquet', kind='dataset', otype='DataFrame', size=103
15, hash='9VU_toJu0mQ3tqdMjHyUkg', n_files=None, n_observations=3, extra_data=None, branch_id=1, cre
ated_on_id=1, space_id=1, storage_id=1, run_id=2, schema_id=None, created_by_id=1, created_at=2026-0
9-15 07:25:23 UTC, is_locked=False, version_tag=None, is_latest=True); to track this artifact as an
input, use: ln.Artifact.get()
→ loaded Transform('Kf6ezGuQyCmq0000', key='scripts/my_workflow_with_step.py'), started n
ew Run('XgwfofABLtytCr0W', entrypoint='subset_dataframe') at 2026-09-15 07:25:31 UTC
→ params: art
ifact='Artifact[Ltugp64VksWVApsK0000]', subset_rows=2, subset_cols=2
The lineage of the subsetted artifact resolves the subsetting step:
subsetted_artifact = ln.Artifact.get(key="my_analysis/dataset_subsetted.parquet")
subsetted_artifact.view_lineage()
Show code cell output
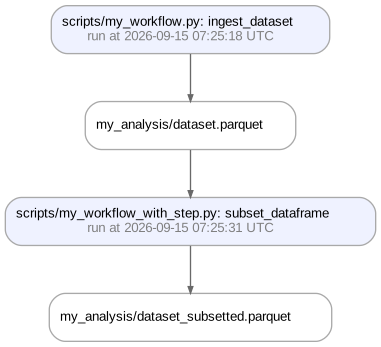
This is the run that created the subsetted_artifact:
subsetted_artifact.run
Show code cell output
Run(uid='XgwfofABLtytCr0W', name=None, description=None, entrypoint='subset_dataframe', started_at=2026-09-15 07:25:31 UTC, finished_at=2026-09-15 07:25:32 UTC, params={'artifact': 'Artifact[Ltugp64VksWVApsK0000]', 'subset_rows': 2, 'subset_cols': 2}, extra_data=None, reference=None, reference_type=None, cli_args=None, branch_id=1, created_on_id=1, space_id=1, transform_id=3, report_id=None, environment_id=None, plan_id=None, created_by_id=1, initiated_by_run_id=3, created_at=2026-09-15 07:25:31 UTC, is_locked=False)
This is the initating run that triggered the function call:
subsetted_artifact.run.initiated_by_run
Show code cell output
Run(uid='2rSxYvcl04XTGgXK', name=None, description=None, entrypoint='ingest_dataset', started_at=2026-09-15 07:25:26 UTC, finished_at=2026-09-15 07:25:32 UTC, params={'key': 'my_analysis/dataset.parquet', 'subset': True}, extra_data=None, reference=None, reference_type=None, cli_args=None, branch_id=1, created_on_id=1, space_id=1, transform_id=3, report_id=6, environment_id=2, plan_id=None, created_by_id=1, initiated_by_run_id=None, created_at=2026-09-15 07:25:26 UTC, is_locked=False)
These are the parameters of the run:
subsetted_artifact.run.params
Show code cell output
{'artifact': 'Artifact[Ltugp64VksWVApsK0000]',
 'subset_rows': 2,
 'subset_cols': 2}
These are the input artifacts:
subsetted_artifact.run.input_artifacts.to_dataframe()
Show code cell output
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 3 | Ltugp64VksWVApsK0000 | my_analysis/dataset.parquet | None | .parquet | dataset | DataFrame | 10315 | 9VU_toJu0mQ3tqdMjHyUkg | None | 3 | ... | True | False | 2026-09-15 07:25:23.300000+00:00 | 1 | 1 | 1 | 1 | 2 | None | 1 |
1 rows × 22 columns
These are output artifacts:
subsetted_artifact.run.output_artifacts.to_dataframe()
Show code cell output
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 5 | LKe31hdmiWUEPegd0000 | my_analysis/dataset_subsetted.parquet | None | .parquet | dataset | DataFrame | 3677 | J0YX05CsehaJ16RhEf6DoQ | None | 2 | ... | True | False | 2026-09-15 07:25:32.788000+00:00 | 1 | 1 | 1 | 1 | 4 | None | 1 |
1 rows × 22 columns
A workflow with CLI arguments
Let’s use click to parse CLI arguments:
import click
import lamindb as ln


@click.command()
@click.option("--key", required=True)
@ln.flow()
def main(key: str):
    df = ln.examples.datasets.mini_immuno.get_dataset2()
    ln.Artifact.from_dataframe(df, key=key).save()


if __name__ == "__main__":
    main()
Let’s run the workflow:
python scripts/my_workflow_with_click.py --key my_analysis/dataset2.parquet
Show code cell output
→ connected lamindb: testuser1/docs
→ script invoked with: --key my_analysis/dataset2.parquet
→ created Transform('7ZjdHjT0MTkm0000', key='scripts/my_workflow_with_click.py'), started
 new Run('PKzNw2PLGxGZfCUD', entrypoint='main') at 2026-09-15 07:25:35 UTC
→ params: key='my_analy
sis/dataset2.parquet'
• tip: to identify the script across renames, pass the uid: @ln.flow(uid="7ZjdHjT0MTkm")
CLI arguments are tracked and accessible via run.cli_args:
run = ln.Run.filter(transform__key__endswith="my_workflow_with_click.py").first()
run.describe()
Show code cell output
Run: PKzNw2P (scripts/my_workflow_with_click.py)
├── uid: PKzNw2PLGxGZfCUD                transform: scripts/my_workflow_with_click.py (0000)
│   started_at: 2026-09-15 07:25:36 UTC  finished_at: 2026-09-15 07:25:40 UTC
│   status: completed
│   branch: main                         space: all
│   created_at: 2026-09-15 07:25:36 UTC  created_by: testuser1
├── cli_args:
│   │ --key my_analysis/dataset2.parquet
├── report: jUXK6Fm
│   │ → connected lamindb: testuser1/docs
│   │ → created Transform('7ZjdHjT0MTkm0000', key='scripts/my_workflow_with_click.py') …
│   │ → params: key='my_analysis/dataset2.parquet'
│   │ • tip: to identify the script across renames, pass the uid: @ln.flow(uid="7ZjdHj …
├── environment: GHGsyn7
│   │ aiobotocore==3.9.1
│   │ aiohappyeyeballs==2.7.1
│   │ aiohttp==3.14.3
│   │ aioitertools==0.13.0
│   │ …
└── Params
    └── key: my_analysis/dataset2.parquet
Note that it doesn’t matter whether you use click, argparse, or any other CLI argument parser.
Track parameters & features
We just saw that the function decorators @ln.flow() and @ln.step() track parameter values automatically. Here is how to pass parameters to ln.track():
import argparse
import lamindb as ln

if __name__ == "__main__":
    p = argparse.ArgumentParser()
    p.add_argument("--input-dir", type=str)
    p.add_argument("--downsample", action="store_true")
    p.add_argument("--learning-rate", type=float)
    args = p.parse_args()
    params = {
        "input_dir": args.input_dir,
        "learning_rate": args.learning_rate,
        "preprocess_params": {
            "downsample": args.downsample,
            "normalization": "the_good_one",
        },
    }
    ln.track(params=params)

    # your code

    ln.finish()
Run the script.
python scripts/run_track_with_params.py --input-dir ./mydataset --learning-rate 0.01 --downsample
Show code cell output
→ connected lamindb: testuser1/docs
→ script invoked with: --input-dir ./mydataset --learning-rate 0.01 --downsample
→ created Transform('bPGFs3iHkHMg0000', key='scripts/run_track_with_params.py'), started
new Run('2IrMhVToEelmsmMy') at 2026-09-15 07:25:42 UTC
→ params: input_dir='./mydataset', learning
_rate=0.01, preprocess_params={'downsample': True, 'normalization': 'the_good_one'}
• tip: to identify the script across renames, pass the uid: ln.track("bPGFs3iHkHMg", para
ms={...})
Query for all runs that match certain parameters:
ln.Run.filter(
    params__learning_rate=0.01,
    params__preprocess_params__downsample=True,
).to_dataframe()
Show code cell output
| uid | name | description | entrypoint | started_at | finished_at | params | extra_data | reference | reference_type | ... | created_at | branch_id | created_on_id | space_id | transform_id | report_id | environment_id | plan_id | created_by_id | initiated_by_run_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 6 | 2IrMhVToEelmsmMy | None | None | None | 2026-09-15 07:25:43.622000+00:00 | 2026-09-15 07:25:46.206801+00:00 | {'input_dir': './mydataset', 'learning_rate': ... | None | None | None | ... | 2026-09-15 07:25:43.622000+00:00 | 1 | 1 | 1 | 5 | 9 | 2 | None | 1 | None |
1 rows × 22 columns
Describe & get parameters:
run = ln.Run.filter(params__learning_rate=0.01).order_by("-started_at").first()
run.describe()
run.params
Show code cell output
Run: 2IrMhVT (scripts/run_track_with_params.py)
├── uid: 2IrMhVToEelmsmMy                transform: scripts/run_track_with_params.py (0000)
│   started_at: 2026-09-15 07:25:43 UTC  finished_at: 2026-09-15 07:25:46 UTC
│   status: completed
│   branch: main                         space: all
│   created_at: 2026-09-15 07:25:43 UTC  created_by: testuser1
├── cli_args:
│   │ --input-dir ./mydataset --learning-rate 0.01 --downsample
├── report: KceeJX2
│   │ → connected lamindb: testuser1/docs
│   │ → created Transform('bPGFs3iHkHMg0000', key='scripts/run_track_with_params.py'), …
│   │ → params: input_dir='./mydataset', learning_rate=0.01, preprocess_params={'downs …
│   │ • tip: to identify the script across renames, pass the uid: ln.track("bPGFs3iHkH …
├── environment: GHGsyn7
│   │ aiobotocore==3.9.1
│   │ aiohappyeyeballs==2.7.1
│   │ aiohttp==3.14.3
│   │ aioitertools==0.13.0
│   │ …
└── Params
    ├── input_dir: ./mydataset
    ├── learning_rate: 0.01
    └── preprocess_params: {'downsample': True, 'normalization': 'the_good_one'}
{'input_dir': './mydataset',
 'learning_rate': 0.01,
 'preprocess_params': {'downsample': True, 'normalization': 'the_good_one'}}
You can also access the CLI arguments used to start the run directly:
run.cli_args
Show code cell output
'--input-dir ./mydataset --learning-rate 0.01 --downsample'
You can also track run features in analogy to artifact features.
In contrast to params, features are validated against the Feature registry and allow to express relationships with entities in your registries.
Let’s first define labels & features.
experiment_type = ln.Record(name="Experiments", is_type=True).save()
experiment_label = ln.Record(name="Experiment1", type=experiment_type).save()
ln.Feature(name="s3_folder", dtype=str).save()
ln.Feature(name="experiment", dtype=experiment_type).save()
Show code cell output
! tip: pass `type` to map record into a type hierarchy
! tip: pass `type` to map feature into a type hierarchy
! tip: pass `type` to map feature into a type hierarchy
Feature(uid='DlBqGKSCbnMt', is_type=False, name='experiment', _dtype_str='cat[Record[KNEn2TvaSpuhfTfg]]', unit=None, description=None, array_rank=0, array_size=0, array_shape=None, synonyms=None, default_value=None, nullable=True, coerce=None, branch_id=1, created_on_id=1, space_id=1, created_by_id=1, run_id=1, type_id=None, created_at=2026-09-15 07:25:46 UTC, is_locked=False)
python scripts/run_track_with_features_and_params.py --s3-folder s3://my-bucket/my-folder --experiment Experiment1
Show code cell output
→ connected lamindb: testuser1/docs
→ script invoked with: --s3-folder s3://my-bucket/my-folder --experiment Experiment1
→ created Transform('PeEsy8doRhxr0000', key='scripts/run_track_with_features_and_params.p
y'), started new Run('EQpjR8kC2erby3CQ') at 2026-09-15 07:25:48 UTC
→ params: example_param=42
→
features: s3_folder='s3://my-bucket/my-folder', experiment='Experiment1'
• tip: to identify the script across renames, pass the uid: ln.track("PeEsy8doRhxr", para
ms={...})
ln.Run.filter(s3_folder="s3://my-bucket/my-folder").to_dataframe()
Show code cell output
| uid | name | description | entrypoint | started_at | finished_at | params | extra_data | reference | reference_type | ... | created_at | branch_id | created_on_id | space_id | transform_id | report_id | environment_id | plan_id | created_by_id | initiated_by_run_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 7 | EQpjR8kC2erby3CQ | None | None | None | 2026-09-15 07:25:49.071000+00:00 | 2026-09-15 07:25:51.786577+00:00 | {'example_param': 42} | None | None | None | ... | 2026-09-15 07:25:49.071000+00:00 | 1 | 1 | 1 | 6 | 10 | 2 | None | 1 | None |
1 rows × 22 columns
Describe & get feature values.
run2 = ln.Run.filter(
    s3_folder="s3://my-bucket/my-folder", experiment="Experiment1"
).last()
run2.describe()
run2.features.get_values()
Show code cell output
Run: EQpjR8k (scripts/run_track_with_features_and_params.py)
├── uid: EQpjR8kC2erby3CQ                transform: scripts/run_track_with_features_and_params.py (0000)
│   started_at: 2026-09-15 07:25:49 UTC  finished_at: 2026-09-15 07:25:51 UTC
│   status: completed
│   branch: main                         space: all
│   created_at: 2026-09-15 07:25:49 UTC  created_by: testuser1
├── cli_args:
│   │ --s3-folder s3://my-bucket/my-folder --experiment Experiment1
├── report: w2SkZG4
│   │ → connected lamindb: testuser1/docs
│   │ → created Transform('PeEsy8doRhxr0000', key='scripts/run_track_with_features_and …
│   │ → params: example_param=42
│   │ → features: s3_folder='s3://my-bucket/my-folder', experiment='Experiment1'
│   │ …
├── environment: GHGsyn7
│   │ aiobotocore==3.9.1
│   │ aiohappyeyeballs==2.7.1
│   │ aiohttp==3.14.3
│   │ aioitertools==0.13.0
│   │ …
├── Params
│   └── example_param: 42
└── Features
    └── experiment                     Record[Experiments]                  Experiment1
        s3_folder                      str                                  s3://my-bucket/my-folder
{'experiment': 'Experiment1', 's3_folder': 's3://my-bucket/my-folder'}
Manage functions in scripts and notebooks
If you want more-fined-grained data lineage tracking in a script or notebook where you called ln.track(), you can also use the step() decorator.
In a notebook
@ln.step()
def subset_dataframe(
    input_artifact_key: str,
    output_artifact_key: str,
    subset_rows: int = 2,
    subset_cols: int = 2,
) -> None:
    artifact = ln.Artifact.get(key=input_artifact_key)
    dataset = artifact.load()
    new_data = dataset.iloc[:subset_rows, :subset_cols]
    ln.Artifact.from_dataframe(new_data, key=output_artifact_key).save()
Prepare a test dataset:
df = ln.examples.datasets.mini_immuno.get_dataset1(otype="DataFrame")
input_artifact_key = "my_analysis/dataset.parquet"
artifact = ln.Artifact.from_dataframe(df, key=input_artifact_key).save()
Show code cell output
→ returning artifact with same hash: Artifact(uid='Ltugp64VksWVApsK0000', key='my_analysis/dataset.parquet', description=None, suffix='.parquet', kind='dataset', otype='DataFrame', size=10315, hash='9VU_toJu0mQ3tqdMjHyUkg', n_files=None, n_observations=3, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=2, schema_id=None, created_by_id=1, created_at=2026-09-15 07:25:23 UTC, is_locked=False, version_tag=None, is_latest=True); to track this artifact as an input, use: ln.Artifact.get()
Run the function with default params:
ouput_artifact_key = input_artifact_key.replace(".parquet", "_subsetted.parquet")
subset_dataframe(input_artifact_key, ouput_artifact_key, subset_rows=1)
Show code cell output
→ ignoring transform with same filename in different folder:
    scDZ6zghkXU50000 → track.ipynb
→ created Transform('abKnIwY1ny7e0000', key='track.ipynb'), started new Run('IyH8KEhLLsZ9rVbv', entrypoint='subset_dataframe') at 2026-09-15 07:25:54 UTC
→ params: input_artifact_key='my_analysis/dataset.parquet', output_artifact_key='my_analysis/dataset_subsetted.parquet', subset_rows=1, subset_cols=2
→ creating new artifact version for key 'my_analysis/dataset_subsetted.parquet' in storage '/home/runner/work/lamindb/lamindb/docs/storage'
Query for the output:
subsetted_artifact = ln.Artifact.get(key=ouput_artifact_key)
subsetted_artifact.view_lineage()
Show code cell output
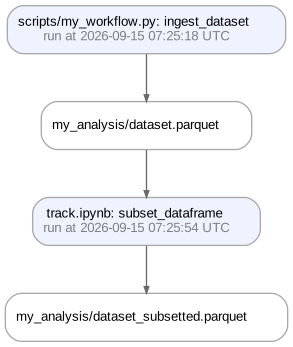
Re-run the function with a different parameter:
subsetted_artifact = subset_dataframe(
    input_artifact_key, ouput_artifact_key, subset_cols=3
)
subsetted_artifact = ln.Artifact.get(key=ouput_artifact_key)
subsetted_artifact.view_lineage()
Show code cell output
→ loaded Transform('abKnIwY1ny7e0000', key='track.ipynb'), started new Run('eMN2Fs4bTdksXVPE', entrypoint='subset_dataframe') at 2026-09-15 07:25:55 UTC
→ params: input_artifact_key='my_analysis/dataset.parquet', output_artifact_key='my_analysis/dataset_subsetted.parquet', subset_rows=2, subset_cols=3
→ creating new artifact version for key 'my_analysis/dataset_subsetted.parquet' in storage '/home/runner/work/lamindb/lamindb/docs/storage'
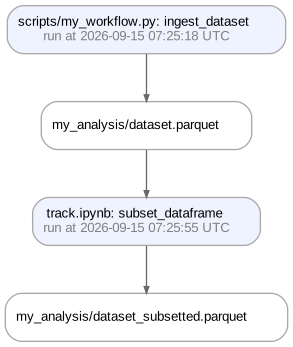
We created a new run:
subsetted_artifact.run
Show code cell output
Run(uid='eMN2Fs4bTdksXVPE', name=None, description=None, entrypoint='subset_dataframe', started_at=2026-09-15 07:25:55 UTC, finished_at=2026-09-15 07:25:57 UTC, params={'input_artifact_key': 'my_analysis/dataset.parquet', 'output_artifact_key': 'my_analysis/dataset_subsetted.parquet', 'subset_rows': 2, 'subset_cols': 3}, extra_data=None, reference=None, reference_type=None, cli_args=None, branch_id=1, created_on_id=1, space_id=1, transform_id=7, report_id=None, environment_id=None, plan_id=None, created_by_id=1, initiated_by_run_id=1, created_at=2026-09-15 07:25:55 UTC, is_locked=False)
With new parameters:
subsetted_artifact.run.params
Show code cell output
{'input_artifact_key': 'my_analysis/dataset.parquet',
 'output_artifact_key': 'my_analysis/dataset_subsetted.parquet',
 'subset_rows': 2,
 'subset_cols': 3}
And a new version of the output artifact:
subsetted_artifact.run.output_artifacts.to_dataframe()
Show code cell output
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 12 | LKe31hdmiWUEPegd0002 | my_analysis/dataset_subsetted.parquet | None | .parquet | dataset | DataFrame | 4299 | aYJEUiAj3bJ0RkaA0Xp1qQ | None | 2 | ... | True | False | 2026-09-15 07:25:57.205000+00:00 | 1 | 1 | 1 | 1 | 9 | None | 1 |
1 rows × 22 columns
In a script
import argparse
import lamindb as ln


@ln.step()
def subset_dataframe(
    artifact: ln.Artifact,
    subset_rows: int = 2,
    subset_cols: int = 2,
    run: ln.Run | None = None,
) -> ln.Artifact:
    dataset = artifact.load(is_run_input=run)
    new_data = dataset.iloc[:subset_rows, :subset_cols]
    new_key = artifact.key.replace(".parquet", "_subsetted.parquet")
    return ln.Artifact.from_dataframe(new_data, key=new_key, run=run).save()


if __name__ == "__main__":
    p = argparse.ArgumentParser()
    p.add_argument("--subset", action="store_true")
    args = p.parse_args()

    params = {"is_subset": args.subset}

    ln.track(params=params)

    if args.subset:
        df = ln.examples.datasets.mini_immuno.get_dataset1(otype="DataFrame")
        artifact = ln.Artifact.from_dataframe(
            df, key="my_analysis/dataset.parquet"
        ).save()
        subsetted_artifact = subset_dataframe(artifact)

    ln.finish()
python scripts/run_script_with_step.py --subset
Show code cell output
→ connected lamindb: testuser1/docs
→ script invoked with: --subset
→ created Transform('oclofmeXV9HZ0000', key='scripts/run_script_with_step.py'), started n
ew Run('a1mx7PPKVTJbCRmb') at 2026-09-15 07:25:58 UTC
→ params: is_subset=True
• tip: to identify the script across renames, pass the uid: ln.track("oclofmeXV9HZ", para
ms={...})
→ returning artifact with same hash: Artifact(uid='Ltugp64VksWVApsK0000', key='my_analysi
s/dataset.parquet', description=None, suffix='.parquet', kind='dataset', otype='DataFrame', size=103
15, hash='9VU_toJu0mQ3tqdMjHyUkg', n_files=None, n_observations=3, extra_data=None, branch_id=1, cre
ated_on_id=1, space_id=1, storage_id=1, run_id=2, schema_id=None, created_by_id=1, created_at=2026-0
9-15 07:25:23 UTC, is_locked=False, version_tag=None, is_latest=True); to track this artifact as an
input, use: ln.Artifact.get()
→ script invoked with: --subset
→ loaded Transform('oclofmeXV9HZ0000', key='scripts/run_script_with_step.py'), started ne
w Run('4DXDYbTA0DK1QzFb', entrypoint='subset_dataframe') at 2026-09-15 07:26:04 UTC
→ params: arti
fact='Artifact[Ltugp64VksWVApsK0000]', subset_rows=2, subset_cols=2
→ returning artifact with same hash: Artifact(uid='LKe31hdmiWUEPegd0000', key='my_analysi
s/dataset_subsetted.parquet', description=None, suffix='.parquet', kind='dataset', otype='DataFrame'
, size=3677, hash='J0YX05CsehaJ16RhEf6DoQ', n_files=None, n_observations=2, extra_data=None, branch_
id=1, created_on_id=1, space_id=1, storage_id=1, run_id=4, schema_id=None, created_by_id=1, created_
at=2026-09-15 07:25:32 UTC, is_locked=False, version_tag=None, is_latest=False); to track this artif
act as an input, use: ln.Artifact.get()
! you are saving to a non-latest version of the artifact
ln.view()
Show code cell output
Artifact
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 12 | LKe31hdmiWUEPegd0002 | my_analysis/dataset_subsetted.parquet | None | .parquet | dataset | DataFrame | 4299 | aYJEUiAj3bJ0RkaA0Xp1qQ | None | 2.0 | ... | True | False | 2026-09-15 07:25:57.205000+00:00 | 1 | 1 | 1 | 1 | 9 | None | 1 |
| 11 | LKe31hdmiWUEPegd0001 | my_analysis/dataset_subsetted.parquet | None | .parquet | dataset | DataFrame | 3650 | kqqMRFXsdeYG-XfVNfiR4A | None | 1.0 | ... | False | False | 2026-09-15 07:25:55.695000+00:00 | 1 | 1 | 1 | 1 | 8 | None | 1 |
| 7 | rylqIWCOpbmJvDcV0000 | my_analysis/dataset2.parquet | None | .parquet | dataset | DataFrame | 7019 | sFlbfG5gV-yi8cG-4DGZSg | None | 3.0 | ... | True | False | 2026-09-15 07:25:40.750000+00:00 | 1 | 1 | 1 | 1 | 5 | None | 1 |
| 5 | LKe31hdmiWUEPegd0000 | my_analysis/dataset_subsetted.parquet | None | .parquet | dataset | DataFrame | 3677 | J0YX05CsehaJ16RhEf6DoQ | None | 2.0 | ... | False | False | 2026-09-15 07:25:32.788000+00:00 | 1 | 1 | 1 | 1 | 4 | None | 1 |
| 3 | Ltugp64VksWVApsK0000 | my_analysis/dataset.parquet | None | .parquet | dataset | DataFrame | 10315 | 9VU_toJu0mQ3tqdMjHyUkg | None | 3.0 | ... | True | False | 2026-09-15 07:25:23.300000+00:00 | 1 | 1 | 1 | 1 | 2 | None | 1 |
| 1 | XLZaL6raaKYTTuD40000 | sample.fasta | None | .fasta | NaN | NaN | 11 | 83rEPcAoBHmYiIuyBYrFKg | None | NaN | ... | True | False | 2026-09-15 07:25:14.894000+00:00 | 1 | 1 | 1 | 1 | 1 | None | 1 |
6 rows × 22 columns
Feature
| uid | name | _dtype_str | unit | description | array_rank | array_size | array_shape | synonyms | default_value | ... | coerce | is_locked | is_type | created_at | branch_id | created_on_id | space_id | created_by_id | run_id | type_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 2 | DlBqGKSCbnMt | experiment | cat[Record[KNEn2TvaSpuhfTfg]] | None | None | 0 | 0 | None | None | None | ... | None | False | False | 2026-09-15 07:25:46.648000+00:00 | 1 | 1 | 1 | 1 | 1 | None |
| 1 | 2rQ4fz4dcibT | s3_folder | str | None | None | 0 | 0 | None | None | None | ... | None | False | False | 2026-09-15 07:25:46.634000+00:00 | 1 | 1 | 1 | 1 | 1 | None |
2 rows × 21 columns
Project
| uid | name | description | abbr | url | start_date | end_date | is_locked | is_type | created_at | branch_id | created_on_id | space_id | created_by_id | run_id | type_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | ||||||||||||||||
| 1 | j5cwRbjfl9OV | My project | None | None | None | None | None | False | False | 2026-09-15 07:25:10.337000+00:00 | 1 | 1 | 1 | 1 | None | None |
Record
| uid | name | description | reference | reference_type | extra_data | is_locked | is_type | created_at | branch_id | created_on_id | space_id | created_by_id | type_id | schema_id | run_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | ||||||||||||||||
| 2 | n5OhbhOWiRx63iBw | Experiment1 | None | None | None | None | False | False | 2026-09-15 07:25:46.623000+00:00 | 1 | 1 | 1 | 1 | 1.0 | None | 1 |
| 1 | KNEn2TvaSpuhfTfg | Experiments | None | None | None | None | False | True | 2026-09-15 07:25:46.614000+00:00 | 1 | 1 | 1 | 1 | NaN | None | 1 |
Run
| uid | name | description | entrypoint | started_at | finished_at | params | extra_data | reference | reference_type | ... | created_at | branch_id | created_on_id | space_id | transform_id | report_id | environment_id | plan_id | created_by_id | initiated_by_run_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 11 | 4DXDYbTA0DK1QzFb | None | None | subset_dataframe | 2026-09-15 07:26:04.328000+00:00 | 2026-09-15 07:26:05.734760+00:00 | {'artifact': 'Artifact[Ltugp64VksWVApsK0000]',... | None | None | None | ... | 2026-09-15 07:26:04.328000+00:00 | 1 | 1 | 1 | 8 | NaN | NaN | None | 1 | 10.0 |
| 10 | a1mx7PPKVTJbCRmb | None | None | NaN | 2026-09-15 07:25:59.774000+00:00 | 2026-09-15 07:26:05.736921+00:00 | {'is_subset': True} | None | None | None | ... | 2026-09-15 07:25:59.774000+00:00 | 1 | 1 | 1 | 8 | 13.0 | 2.0 | None | 1 | NaN |
| 9 | eMN2Fs4bTdksXVPE | None | None | subset_dataframe | 2026-09-15 07:25:55.786000+00:00 | 2026-09-15 07:25:57.214213+00:00 | {'input_artifact_key': 'my_analysis/dataset.pa... | None | None | None | ... | 2026-09-15 07:25:55.786000+00:00 | 1 | 1 | 1 | 7 | NaN | NaN | None | 1 | 1.0 |
| 8 | IyH8KEhLLsZ9rVbv | None | None | subset_dataframe | 2026-09-15 07:25:54.283000+00:00 | 2026-09-15 07:25:55.705187+00:00 | {'input_artifact_key': 'my_analysis/dataset.pa... | None | None | None | ... | 2026-09-15 07:25:54.283000+00:00 | 1 | 1 | 1 | 7 | NaN | NaN | None | 1 | 1.0 |
| 7 | EQpjR8kC2erby3CQ | None | None | NaN | 2026-09-15 07:25:49.071000+00:00 | 2026-09-15 07:25:51.786577+00:00 | {'example_param': 42} | None | None | None | ... | 2026-09-15 07:25:49.071000+00:00 | 1 | 1 | 1 | 6 | 10.0 | 2.0 | None | 1 | NaN |
| 6 | 2IrMhVToEelmsmMy | None | None | NaN | 2026-09-15 07:25:43.622000+00:00 | 2026-09-15 07:25:46.206801+00:00 | {'input_dir': './mydataset', 'learning_rate': ... | None | None | None | ... | 2026-09-15 07:25:43.622000+00:00 | 1 | 1 | 1 | 5 | 9.0 | 2.0 | None | 1 | NaN |
| 5 | PKzNw2PLGxGZfCUD | None | None | main | 2026-09-15 07:25:36.312000+00:00 | 2026-09-15 07:25:40.755994+00:00 | {'key': 'my_analysis/dataset2.parquet'} | None | None | None | ... | 2026-09-15 07:25:36.312000+00:00 | 1 | 1 | 1 | 4 | 8.0 | 2.0 | None | 1 | NaN |
7 rows × 22 columns
Storage
| uid | root | description | type | region | instance_uid | is_locked | created_at | branch_id | created_on_id | space_id | created_by_id | run_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||
| 1 | vIqUW4AOSwQB | /home/runner/work/lamindb/lamindb/docs/storage | None | local | None | 3PUOVI0AaHxa | False | 2026-09-15 07:25:08.827000+00:00 | 1 | 1 | 1 | 1 | None |
Transform
| uid | key | description | kind | source_code | hash | reference | reference_type | version_tag | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | environment_id | plan_id | run_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||
| 8 | oclofmeXV9HZ0000 | scripts/run_script_with_step.py | CLI: run_script_with_step.py | script | import argparse\nimport lamindb as ln\n\n\n@ln... | HJbjZyWWczP-VmzKQsSORg | None | None | None | True | False | 2026-09-15 07:25:58.905000+00:00 | 1 | 1 | 1 | None | None | NaN | 1 |
| 7 | abKnIwY1ny7e0000 | track.ipynb | NaN | function | @ln.step()\ndef subset_dataframe(\n input_a... | 5kfRAQLCPwxrvAjspfdp2Q | None | None | None | True | False | 2026-09-15 07:25:54.007000+00:00 | 1 | 1 | 1 | None | None | 1.0 | 1 |
| 6 | PeEsy8doRhxr0000 | scripts/run_track_with_features_and_params.py | CLI: run_track_with_features_and_params.py | script | import argparse\nimport lamindb as ln\n\n\nif ... | 9MjLyvM1QzE2nPIPDRzBwg | None | None | None | True | False | 2026-09-15 07:25:48.224000+00:00 | 1 | 1 | 1 | None | None | NaN | 1 |
| 5 | bPGFs3iHkHMg0000 | scripts/run_track_with_params.py | CLI: run_track_with_params.py | script | import argparse\nimport lamindb as ln\n\nif __... | 5RBz7zJICeKE1OSmg7gEdQ | None | None | None | True | False | 2026-09-15 07:25:42.747000+00:00 | 1 | 1 | 1 | None | None | NaN | 1 |
| 4 | 7ZjdHjT0MTkm0000 | scripts/my_workflow_with_click.py | CLI: my_workflow_with_click.py | script | import click\nimport lamindb as ln\n\n\n@click... | 0eX8wmaAWkuuAvACWwL1Xg | None | None | None | True | False | 2026-09-15 07:25:35.324000+00:00 | 1 | 1 | 1 | None | None | NaN | 1 |
| 3 | Kf6ezGuQyCmq0000 | scripts/my_workflow_with_step.py | NaN | script | import lamindb as ln\n\n\[email protected]()\ndef subs... | Ncx6UswxtCN3FZD86kgcVQ | None | None | None | True | False | 2026-09-15 07:25:25.901000+00:00 | 1 | 1 | 1 | None | None | NaN | 1 |
| 2 | kuHcUQ5HnEdn0000 | scripts/my_workflow.py | NaN | script | import lamindb as ln\n\n\[email protected]()\ndef inge... | uJ3fsnfaNN6EZ7Q0d8SQtw | None | None | None | True | False | 2026-09-15 07:25:17.152000+00:00 | 1 | 1 | 1 | None | None | NaN | 1 |
The database
See the state of the database after we ran these different examples:
ln.view()
Show code cell output
Artifact
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 12 | LKe31hdmiWUEPegd0002 | my_analysis/dataset_subsetted.parquet | None | .parquet | dataset | DataFrame | 4299 | aYJEUiAj3bJ0RkaA0Xp1qQ | None | 2.0 | ... | True | False | 2026-09-15 07:25:57.205000+00:00 | 1 | 1 | 1 | 1 | 9 | None | 1 |
| 11 | LKe31hdmiWUEPegd0001 | my_analysis/dataset_subsetted.parquet | None | .parquet | dataset | DataFrame | 3650 | kqqMRFXsdeYG-XfVNfiR4A | None | 1.0 | ... | False | False | 2026-09-15 07:25:55.695000+00:00 | 1 | 1 | 1 | 1 | 8 | None | 1 |
| 7 | rylqIWCOpbmJvDcV0000 | my_analysis/dataset2.parquet | None | .parquet | dataset | DataFrame | 7019 | sFlbfG5gV-yi8cG-4DGZSg | None | 3.0 | ... | True | False | 2026-09-15 07:25:40.750000+00:00 | 1 | 1 | 1 | 1 | 5 | None | 1 |
| 5 | LKe31hdmiWUEPegd0000 | my_analysis/dataset_subsetted.parquet | None | .parquet | dataset | DataFrame | 3677 | J0YX05CsehaJ16RhEf6DoQ | None | 2.0 | ... | False | False | 2026-09-15 07:25:32.788000+00:00 | 1 | 1 | 1 | 1 | 4 | None | 1 |
| 3 | Ltugp64VksWVApsK0000 | my_analysis/dataset.parquet | None | .parquet | dataset | DataFrame | 10315 | 9VU_toJu0mQ3tqdMjHyUkg | None | 3.0 | ... | True | False | 2026-09-15 07:25:23.300000+00:00 | 1 | 1 | 1 | 1 | 2 | None | 1 |
| 1 | XLZaL6raaKYTTuD40000 | sample.fasta | None | .fasta | NaN | NaN | 11 | 83rEPcAoBHmYiIuyBYrFKg | None | NaN | ... | True | False | 2026-09-15 07:25:14.894000+00:00 | 1 | 1 | 1 | 1 | 1 | None | 1 |
6 rows × 22 columns
Feature
| uid | name | _dtype_str | unit | description | array_rank | array_size | array_shape | synonyms | default_value | ... | coerce | is_locked | is_type | created_at | branch_id | created_on_id | space_id | created_by_id | run_id | type_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 2 | DlBqGKSCbnMt | experiment | cat[Record[KNEn2TvaSpuhfTfg]] | None | None | 0 | 0 | None | None | None | ... | None | False | False | 2026-09-15 07:25:46.648000+00:00 | 1 | 1 | 1 | 1 | 1 | None |
| 1 | 2rQ4fz4dcibT | s3_folder | str | None | None | 0 | 0 | None | None | None | ... | None | False | False | 2026-09-15 07:25:46.634000+00:00 | 1 | 1 | 1 | 1 | 1 | None |
2 rows × 21 columns
Project
| uid | name | description | abbr | url | start_date | end_date | is_locked | is_type | created_at | branch_id | created_on_id | space_id | created_by_id | run_id | type_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | ||||||||||||||||
| 1 | j5cwRbjfl9OV | My project | None | None | None | None | None | False | False | 2026-09-15 07:25:10.337000+00:00 | 1 | 1 | 1 | 1 | None | None |
Record
| uid | name | description | reference | reference_type | extra_data | is_locked | is_type | created_at | branch_id | created_on_id | space_id | created_by_id | type_id | schema_id | run_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | ||||||||||||||||
| 2 | n5OhbhOWiRx63iBw | Experiment1 | None | None | None | None | False | False | 2026-09-15 07:25:46.623000+00:00 | 1 | 1 | 1 | 1 | 1.0 | None | 1 |
| 1 | KNEn2TvaSpuhfTfg | Experiments | None | None | None | None | False | True | 2026-09-15 07:25:46.614000+00:00 | 1 | 1 | 1 | 1 | NaN | None | 1 |
Run
| uid | name | description | entrypoint | started_at | finished_at | params | extra_data | reference | reference_type | ... | created_at | branch_id | created_on_id | space_id | transform_id | report_id | environment_id | plan_id | created_by_id | initiated_by_run_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 11 | 4DXDYbTA0DK1QzFb | None | None | subset_dataframe | 2026-09-15 07:26:04.328000+00:00 | 2026-09-15 07:26:05.734760+00:00 | {'artifact': 'Artifact[Ltugp64VksWVApsK0000]',... | None | None | None | ... | 2026-09-15 07:26:04.328000+00:00 | 1 | 1 | 1 | 8 | NaN | NaN | None | 1 | 10.0 |
| 10 | a1mx7PPKVTJbCRmb | None | None | NaN | 2026-09-15 07:25:59.774000+00:00 | 2026-09-15 07:26:05.736921+00:00 | {'is_subset': True} | None | None | None | ... | 2026-09-15 07:25:59.774000+00:00 | 1 | 1 | 1 | 8 | 13.0 | 2.0 | None | 1 | NaN |
| 9 | eMN2Fs4bTdksXVPE | None | None | subset_dataframe | 2026-09-15 07:25:55.786000+00:00 | 2026-09-15 07:25:57.214213+00:00 | {'input_artifact_key': 'my_analysis/dataset.pa... | None | None | None | ... | 2026-09-15 07:25:55.786000+00:00 | 1 | 1 | 1 | 7 | NaN | NaN | None | 1 | 1.0 |
| 8 | IyH8KEhLLsZ9rVbv | None | None | subset_dataframe | 2026-09-15 07:25:54.283000+00:00 | 2026-09-15 07:25:55.705187+00:00 | {'input_artifact_key': 'my_analysis/dataset.pa... | None | None | None | ... | 2026-09-15 07:25:54.283000+00:00 | 1 | 1 | 1 | 7 | NaN | NaN | None | 1 | 1.0 |
| 7 | EQpjR8kC2erby3CQ | None | None | NaN | 2026-09-15 07:25:49.071000+00:00 | 2026-09-15 07:25:51.786577+00:00 | {'example_param': 42} | None | None | None | ... | 2026-09-15 07:25:49.071000+00:00 | 1 | 1 | 1 | 6 | 10.0 | 2.0 | None | 1 | NaN |
| 6 | 2IrMhVToEelmsmMy | None | None | NaN | 2026-09-15 07:25:43.622000+00:00 | 2026-09-15 07:25:46.206801+00:00 | {'input_dir': './mydataset', 'learning_rate': ... | None | None | None | ... | 2026-09-15 07:25:43.622000+00:00 | 1 | 1 | 1 | 5 | 9.0 | 2.0 | None | 1 | NaN |
| 5 | PKzNw2PLGxGZfCUD | None | None | main | 2026-09-15 07:25:36.312000+00:00 | 2026-09-15 07:25:40.755994+00:00 | {'key': 'my_analysis/dataset2.parquet'} | None | None | None | ... | 2026-09-15 07:25:36.312000+00:00 | 1 | 1 | 1 | 4 | 8.0 | 2.0 | None | 1 | NaN |
7 rows × 22 columns
Storage
| uid | root | description | type | region | instance_uid | is_locked | created_at | branch_id | created_on_id | space_id | created_by_id | run_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||
| 1 | vIqUW4AOSwQB | /home/runner/work/lamindb/lamindb/docs/storage | None | local | None | 3PUOVI0AaHxa | False | 2026-09-15 07:25:08.827000+00:00 | 1 | 1 | 1 | 1 | None |
Transform
| uid | key | description | kind | source_code | hash | reference | reference_type | version_tag | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | environment_id | plan_id | run_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||
| 8 | oclofmeXV9HZ0000 | scripts/run_script_with_step.py | CLI: run_script_with_step.py | script | import argparse\nimport lamindb as ln\n\n\n@ln... | HJbjZyWWczP-VmzKQsSORg | None | None | None | True | False | 2026-09-15 07:25:58.905000+00:00 | 1 | 1 | 1 | None | None | NaN | 1 |
| 7 | abKnIwY1ny7e0000 | track.ipynb | NaN | function | @ln.step()\ndef subset_dataframe(\n input_a... | 5kfRAQLCPwxrvAjspfdp2Q | None | None | None | True | False | 2026-09-15 07:25:54.007000+00:00 | 1 | 1 | 1 | None | None | 1.0 | 1 |
| 6 | PeEsy8doRhxr0000 | scripts/run_track_with_features_and_params.py | CLI: run_track_with_features_and_params.py | script | import argparse\nimport lamindb as ln\n\n\nif ... | 9MjLyvM1QzE2nPIPDRzBwg | None | None | None | True | False | 2026-09-15 07:25:48.224000+00:00 | 1 | 1 | 1 | None | None | NaN | 1 |
| 5 | bPGFs3iHkHMg0000 | scripts/run_track_with_params.py | CLI: run_track_with_params.py | script | import argparse\nimport lamindb as ln\n\nif __... | 5RBz7zJICeKE1OSmg7gEdQ | None | None | None | True | False | 2026-09-15 07:25:42.747000+00:00 | 1 | 1 | 1 | None | None | NaN | 1 |
| 4 | 7ZjdHjT0MTkm0000 | scripts/my_workflow_with_click.py | CLI: my_workflow_with_click.py | script | import click\nimport lamindb as ln\n\n\n@click... | 0eX8wmaAWkuuAvACWwL1Xg | None | None | None | True | False | 2026-09-15 07:25:35.324000+00:00 | 1 | 1 | 1 | None | None | NaN | 1 |
| 3 | Kf6ezGuQyCmq0000 | scripts/my_workflow_with_step.py | NaN | script | import lamindb as ln\n\n\[email protected]()\ndef subs... | Ncx6UswxtCN3FZD86kgcVQ | None | None | None | True | False | 2026-09-15 07:25:25.901000+00:00 | 1 | 1 | 1 | None | None | NaN | 1 |
| 2 | kuHcUQ5HnEdn0000 | scripts/my_workflow.py | NaN | script | import lamindb as ln\n\n\[email protected]()\ndef inge... | uJ3fsnfaNN6EZ7Q0d8SQtw | None | None | None | True | False | 2026-09-15 07:25:17.152000+00:00 | 1 | 1 | 1 | None | None | NaN | 1 |
Using transform versions as templates
A transform acts like a template upon using lamin load to load it. Consider you run:
lamin load https://lamin.ai/account/instance/transform/Akd7gx7Y9oVO0000
Upon running the returned notebook or script, you’ll automatically create a new version and be able to browse it via the version dropdown on the UI.
Additionally, you can:
label using
ULabelorRecord, e.g.,transform.records.add(template_label)tag with an indicative
versionstring, e.g.,transform.version = "T1"; transform.save()
Saving a notebook as an artifact
Sometimes you might want to save a notebook as an artifact. This is how you can do it:
lamin save template1.ipynb --key templates/template1.ipynb --description "Template for analysis type 1" --registry artifact
A few checks at the end of this notebook:
assert run.params == {
    "input_dir": "./mydataset",
    "learning_rate": 0.01,
    "preprocess_params": {"downsample": True, "normalization": "the_good_one"},
}, run.params
assert my_project.artifacts.exists()
assert my_project.transforms.exists()
assert my_project.runs.exists()