Manage records & ontologies 
 
This guide walks you from managing notes to managing structured relational metadata. You can build your ELN & LIMS, your own ontologies, and even a knowledge graph. If you instead want to build on public biological ontologies, read: Manage biological ontologies .
If you haven’t connected a database, create one in a development directory:
lamin init
Show code cell output
→ connected lamindb: testuser1/docs
Save markdown notes
You can save a markdown note as a record:
lamin save <topic>/<my-note.md>
To load a record back as a markdown file, run:
lamin load https://lamin.ai/laminlabs/lamindata/record/mNDJgWFrkWQVW3ox
Create a data record
A data record stores values for Feature objects.
import lamindb as ln

gc_content = ln.Feature(name="gc_content", dtype=float).save()
sample1 = ln.Record(name="Sample 1", features={"gc_content": 0.5}).save()
sample1.describe()
Show code cell output
→ connected lamindb: testuser1/docs
! tip: pass `type` to map feature into a type hierarchy
! tip: pass `type` to map record into a type hierarchy
Record: Sample 1
├── uid: kVikCcq7LnHKAxZh  type:
│   is_type: False         schema:
│   reference:             branch: main
│   space: all             created_at: 2026-10-21 07:42:45 UTC
│   created_by: testuser1
└── Features
    └── gc_content                     float                                0.5
Organize records by type
To create and use a record type call:
experiment_type = ln.Record(name="Experiments", is_type=True).save()
experiment1 = ln.Record(name="Experiment 1", type=experiment_type).save()
Show code cell output
! tip: pass `type` to map record into a type hierarchy
→ returning record with same name: 'Experiments'
! you are trying to create a record with name='Experiment 1' but a record with similar name exists: 'Experiment1'. Did you mean to load it?
You can define a feature whose dtype is a record type:
experiment = ln.Feature(name="experiment", dtype=experiment_type).save()
Show code cell output
! tip: pass `type` to map feature into a type hierarchy
→ returning feature with same name: 'experiment'
to_dataframe() exports:
experiment_type.to_dataframe()
Show code cell output
→ exporting 2 records of 'Experiments'
| __lamindb_record_uid__ | __lamindb_record_name__ | |
|---|---|---|
| __lamindb_record_id__ | ||
| 2 | 0yVDmOCdMfT3UsEX | Experiment1 |
| 6 | dJszBTKaF9hEPC5i | Experiment 1 |
Constrain records with a schema
A Schema turns the type into a frame and validates the features of its data records:
schema = ln.Schema(
    [experiment, gc_content.with_config(optional=True)],
).save()
samplesheet = ln.Record(name="Samples", is_type=True, schema=schema).save()
Show code cell output
! tip: pass `type` to map record into a type hierarchy
! you are trying to create a record with name='Samples' but a record with similar name exists: 'Sample 1'. Did you mean to load it?
experiment is required, so setting only gc_content raises ValidationError:
try:
    sample2 = ln.Record(
        name="Sample 2",
        type=samplesheet,
        features={gc_content: 0.6},
    ).save()
except ln.errors.ValidationError as error:
    print(error)
Show code cell output
Cannot set type to 'Samples' on Record 'Sample 2': missing required features 'experiment'
Also moving sample into samplesheet raises since it only has gc_content:
try:
    sample1.type = samplesheet
except ln.errors.ValidationError as error:
    print(error)

# set required featured on sample1
sample1.features.set_values({
    experiment: experiment1,
    gc_content: 0.5,
})

# move sample1 into the samplesheet
sample1.type = samplesheet
sample1.save()
Show code cell output
Cannot set type to 'Samples' on Record 'Sample 1': missing required features 'experiment'
Record(uid='kVikCcq7LnHKAxZh', is_type=False, name='Sample 1', description=None, reference=None, reference_type=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, created_by_id=1, type_id=7, schema_id=None, run_id=None, created_at=2026-10-21 07:42:45 UTC, is_locked=False)
To replace selected feature values while preserving other annotations, use
update_values():
sample1.features.update_values({gc_content: 0.6})
Use a feature as an index
You can set an index for a schema via index:
sample_abbr = ln.Feature(name="sample_abbr", dtype=str).save()
score = ln.Feature(name="score", dtype=float).save()
schema_with_index = ln.Schema(features=[score], index=sample_abbr).save()
frame_with_index = ln.Record(
    name="Indexed samples", is_type=True, schema=schema_with_index
).save()
record = ln.Record(
    features={"sample_abbr": "S-001", "score": 1.5},
    type=frame_with_index,
).save()
Show code cell output
! tip: pass `type` to map feature into a type hierarchy
! tip: pass `type` to map feature into a type hierarchy
! tip: pass `type` to map record into a type hierarchy
Inspect the dataframe:
frame_with_index.to_dataframe()
Show code cell output
→ exporting 1 records of 'Indexed samples'
| score | |
|---|---|
| sample_abbr | |
| S-001 | 1.5 |
Import records from a dataframe
from_dataframe() creates one data record per row. A new type name creates a record frame and infers its schema:
import pandas as pd

records = ln.Record.from_dataframe(
    pd.DataFrame({"gc_content": [0.1, 0.2]}),
    type="my_df",
).save()
records
Show code cell output
! tip: pass `type` to map record into a type hierarchy
! tip: pass `type` to map schema into a type hierarchy
! tip: pass `type` to map schema into a type hierarchy
SQLRecordList([Record(uid='olocaDyz5AZgcRXy', is_type=False, name=None, description=None, reference=None, reference_type=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, created_by_id=1, type_id=11, schema_id=None, run_id=None, created_at=2026-10-21 07:42:47 UTC, is_locked=False),
               Record(uid='GFJ0cGGd6o8xzAgd', is_type=False, name=None, description=None, reference=None, reference_type=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, created_by_id=1, type_id=11, schema_id=None, run_id=None, created_at=2026-10-21 07:42:47 UTC, is_locked=False)])
Pass an existing record frame as type to import into it. With no schema index, a __lamindb_record_name__ column sets the record name:
ln.Record.from_dataframe(
    pd.DataFrame(
        {
            "__lamindb_record_name__": ["Imported sample"],
            "experiment": ["Experiment 1"],
            "gc_content": [0.45],
        }
    ),
    type=samplesheet,
).save()
Show code cell output
SQLRecordList([Record(uid='0vMwRYCBODsDgduU', is_type=False, name='Imported sample', description=None, reference=None, reference_type=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, created_by_id=1, type_id=7, schema_id=None, run_id=None, created_at=2026-10-21 07:42:47 UTC, is_locked=False)])
Query records
Filter with a feature expression, or by a field such as type:
ln.Record.filter(gc_content == 0.5).to_dataframe(include="features")
Show code cell output
! falling back to generic Record queryset export because the queryset does not resolve to exactly one non-null `type_id`
| uid | id | name |
|---|
ln.Record.filter(gc_content > 0.4).to_dataframe(include="features")
Show code cell output
→ exporting 2 records of 'Samples'
| experiment | gc_content | __lamindb_record_uid__ | __lamindb_record_name__ | |
|---|---|---|---|---|
| __lamindb_record_id__ | ||||
| 5 | Experiment 1 | 0.60 | kVikCcq7LnHKAxZh | Sample 1 |
| 14 | Experiment 1 | 0.45 | 0vMwRYCBODsDgduU | Imported sample |
ln.Record.filter(type=samplesheet).to_dataframe(include="features")
Show code cell output
→ exporting 2 records of 'Samples'
| experiment | gc_content | __lamindb_record_uid__ | __lamindb_record_name__ | |
|---|---|---|---|---|
| __lamindb_record_id__ | ||||
| 5 | Experiment 1 | 0.60 | kVikCcq7LnHKAxZh | Sample 1 |
| 14 | Experiment 1 | 0.45 | 0vMwRYCBODsDgduU | Imported sample |
Link transforms to a record
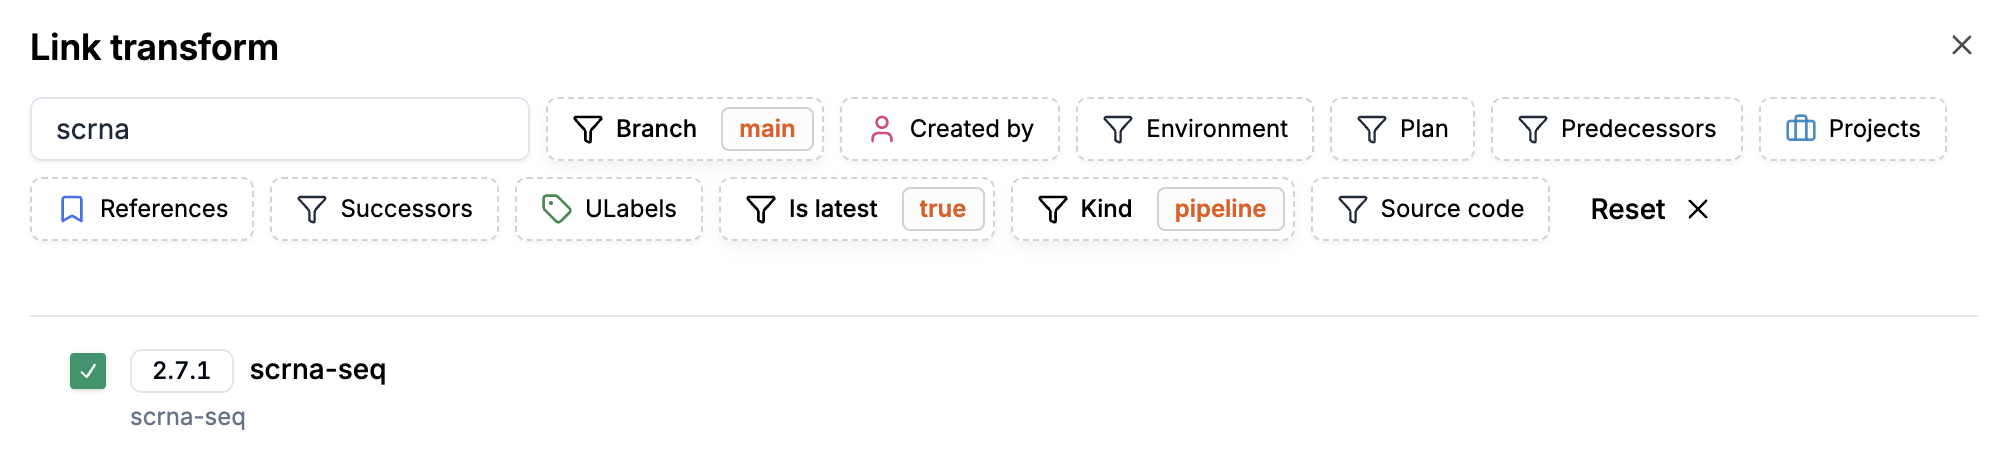
Click on the “Link” button in the “Transforms” card of the record page, e.g., here: https://lamin.ai/laminlabs/lamindata/record/mPiUOc67hQAw4Pgz
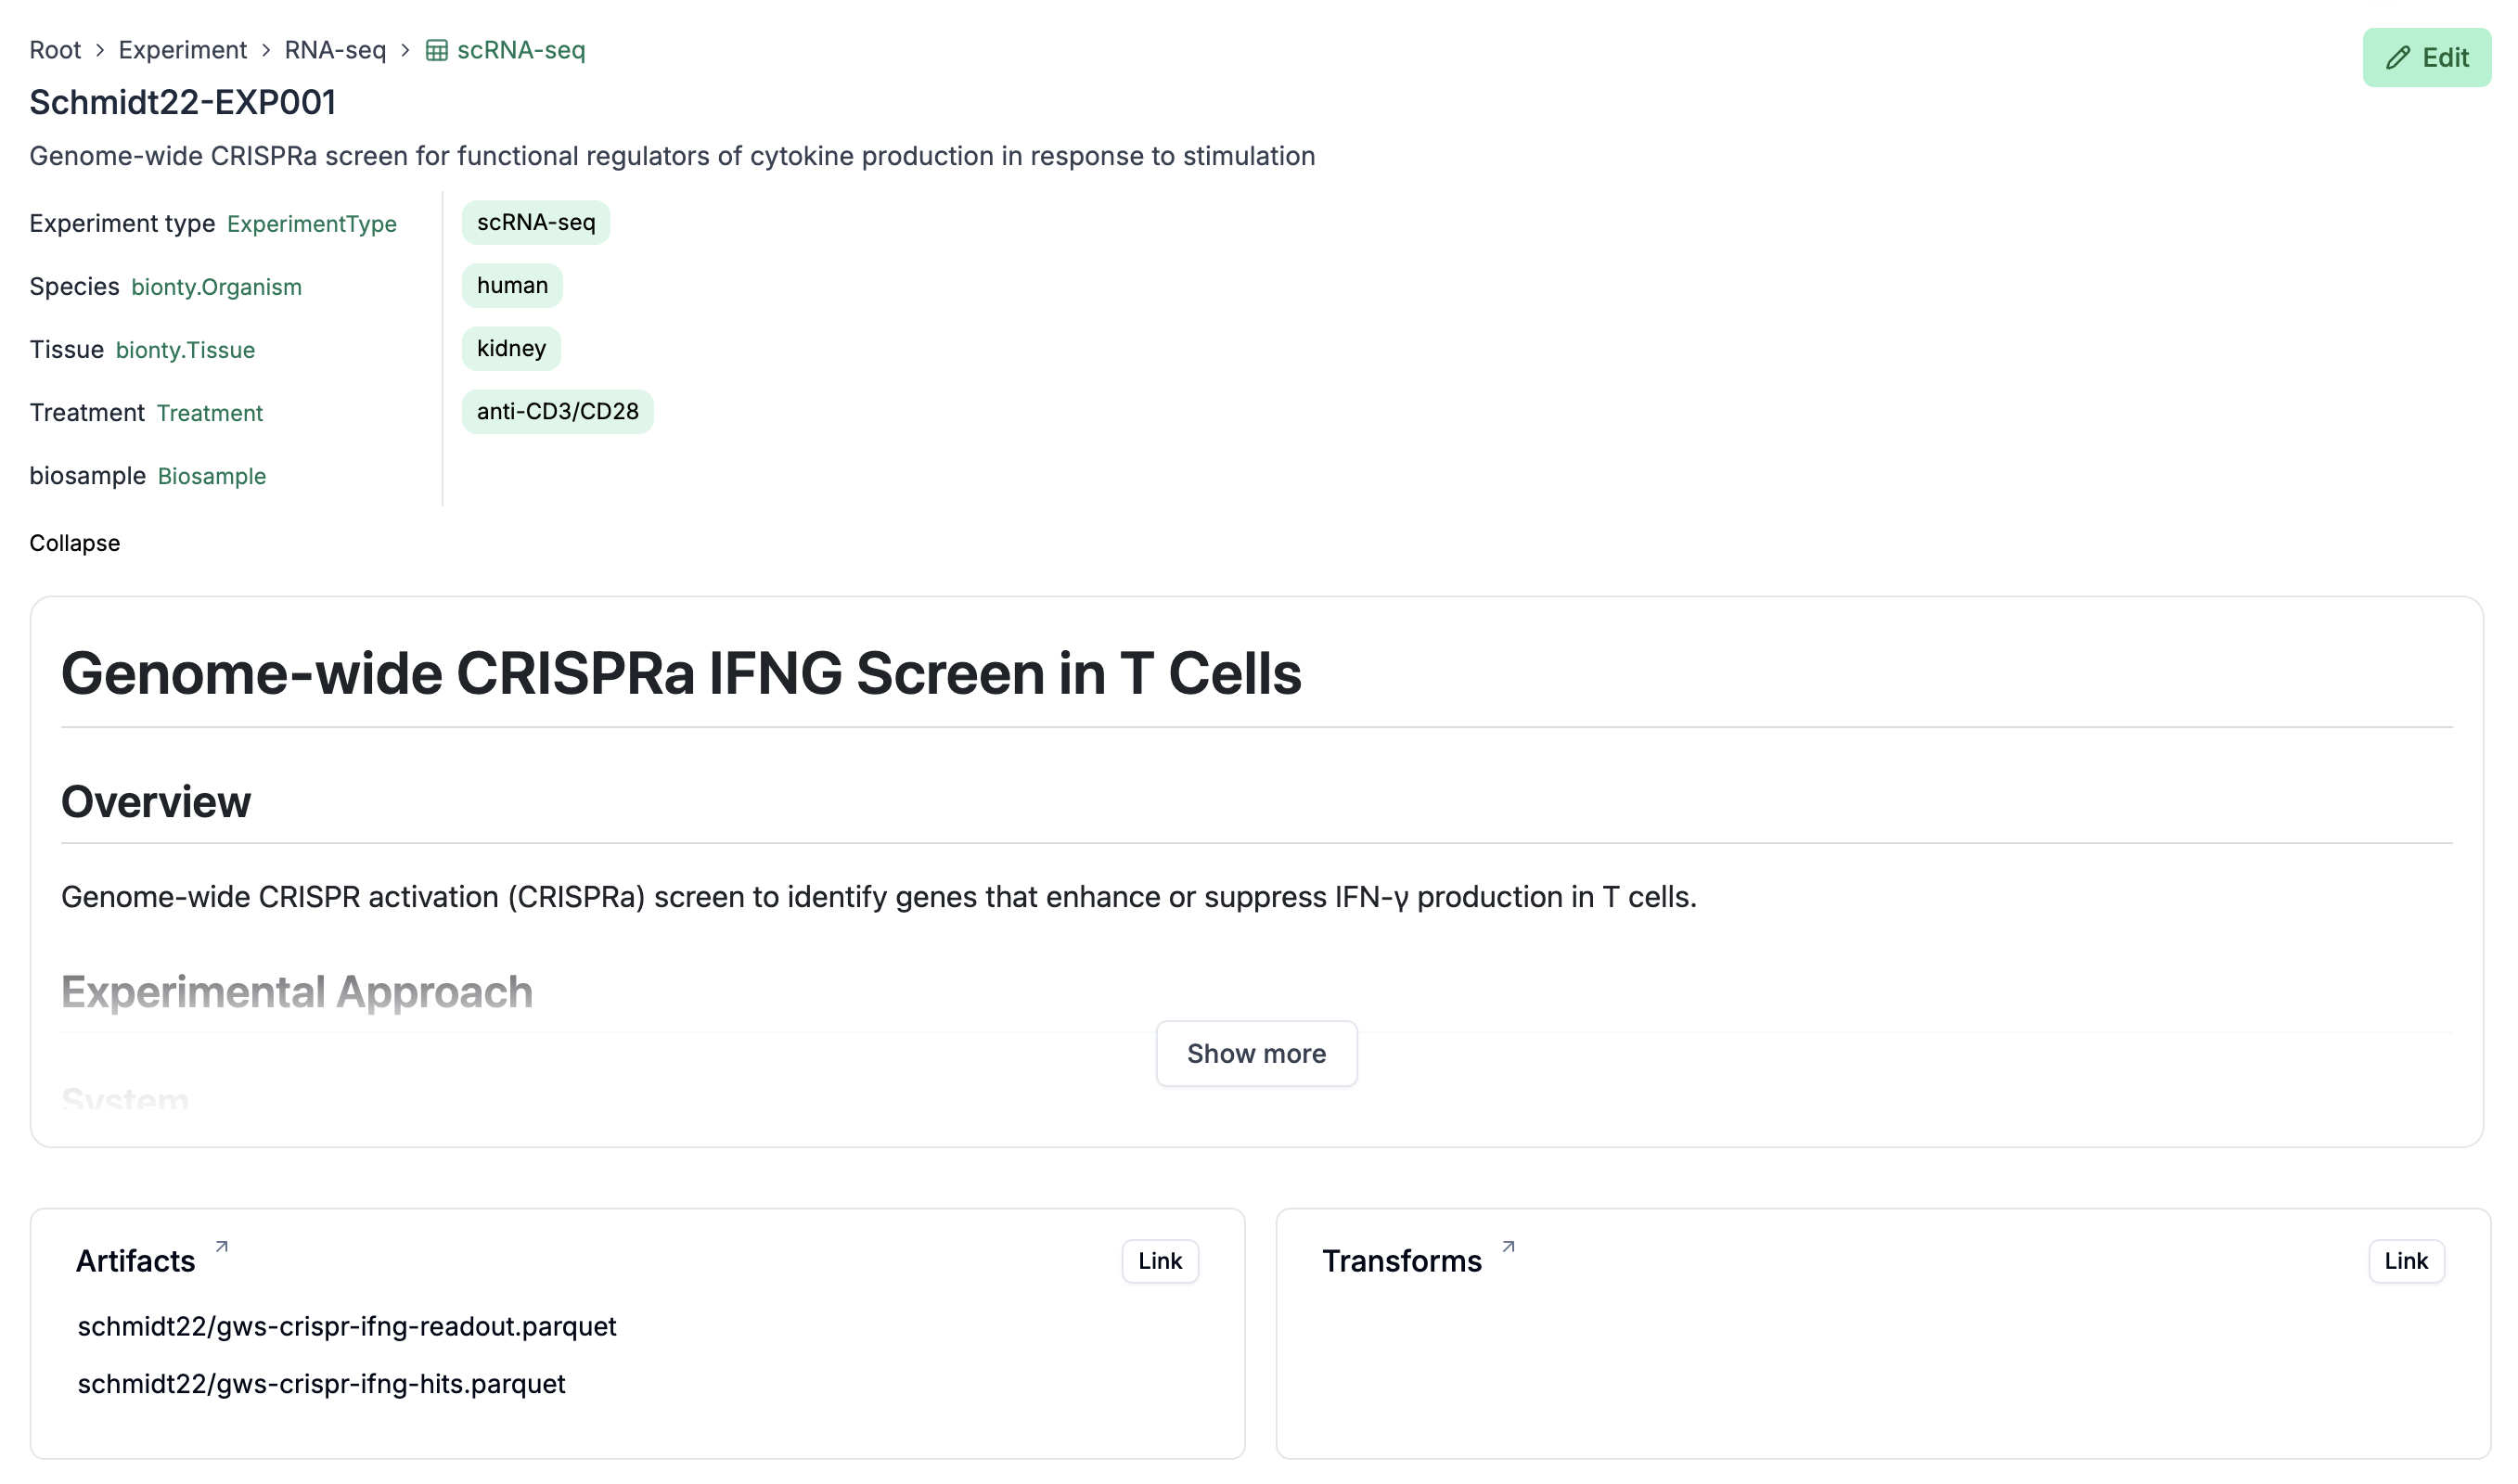
Select a transform:
You can now launch the transform via the small “Launch” button, directly from the record:
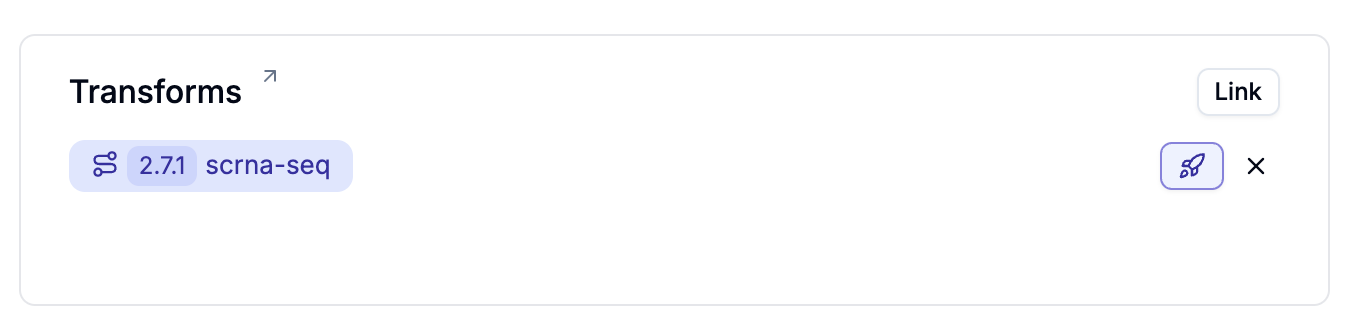
Export record frames as artifacts
Click on “Export to Artifact” to save all data records under a type as an artifact.
In the API, call to_artifact() on a record frame:
experiment_type.to_artifact()
Show code cell output
→ exporting 2 records of 'Experiments'
Artifact(uid='hfNa1zRtdDUdqdfr0000', key='lamindb_record_exports/Experiments.csv', description='Export of record type WBI2SiqOQyuhFE9t', suffix='.csv', kind='dataset', otype='DataFrame', size=106, hash='7AVpQqJmqYbs3xsXCQe-rg', n_files=None, n_observations=2, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=14, schema_id=None, created_by_id=1, created_at=2026-10-21 07:42:47 UTC, is_locked=False, version_tag=None, is_latest=True)