Generate single-cell images 
 
Here, we are going to process the previously ingested microscopy images with the scPortrait pipeline to generate single-cell images that we can use to assess autophagosome formation at a single-cell level.
import lamindb as ln
from collections.abc import Iterable

from pathlib import Path
from scportrait.pipeline.extraction import HDF5CellExtraction
from scportrait.pipeline.project import Project
from scportrait.pipeline.segmentation.workflows import CytosolSegmentationCellpose

ln.track()
Show code cell output
→ connected lamindb: testuser1/test-sc-imaging
→ created Transform('56IaWPrFDRtQ0000', key='sc-imaging2.ipynb'), started new Run('AOhp17JHTOVUi0sf') at 2026-10-21 07:43:30 UTC
• tip: to identify the notebook across renames, pass the uid: ln.track("56IaWPrFDRtQ")
Query microscopy images
First, we query for the raw and annotated microscopy images.
input_images = ln.Artifact.filter(
    ulabels__name="autophagy imaging", description__icontains="raw image", suffix=".tif"
)
The experiment includes two genotypes (WT and EI24KO) under two treatment conditions (unstimulated vs. 14h Torin-1).
Multiple clonal cell lines were imaged for each condition across several fields of view (FOVs) and imaging channels.
We’ll extract single-cell images from each FOV and annotate them with metadata including genotype, treatment condition, clonal cell line, and imaging experiment.
input_images_df = input_images.to_dataframe(features=True)

display(input_images_df.head())

conditions = input_images_df["stimulation"].unique().tolist()
cell_line_clones = input_images_df["cell_line_clone"].unique().tolist()
FOVs = input_images_df["FOV"].unique().tolist()
Show code cell output
! truncated query result to limit=20 Artifact objects
/tmp/ipykernel_3194/1645869880.py:1: DeprecationWarning: `features=True` is deprecated, pass `include="features"` instead.
  input_images_df = input_images.to_dataframe(features=True)
| uid | key | genotype | stimulation | cell_line_clone | channel | FOV | magnification | microscope | imaged structure | resolution | study | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | ||||||||||||
| 49 | AVRTVX9gEu4LrTAP0000 | input_data_imaging_usecase/images/Timepoint001... | EI24KO | untreated | U2OS lcklip-mNeon mCherryLC3B EI24 KO clone 2 | mCherry | FOV2 | 20X | Opera Phenix | mCherry-LC3B | 0.597976 | autophagy imaging |
| 48 | 6uUjyphUD4D1Hixc0000 | input_data_imaging_usecase/images/Timepoint001... | EI24KO | untreated | U2OS lcklip-mNeon mCherryLC3B EI24 KO clone 2 | mCherry | FOV1 | 20X | Opera Phenix | mCherry-LC3B | 0.597976 | autophagy imaging |
| 47 | AhBvnNKg5yJcG6LU0000 | input_data_imaging_usecase/images/Timepoint001... | EI24KO | untreated | U2OS lcklip-mNeon mCherryLC3B EI24 KO clone 2 | DAPI | FOV2 | 20X | Opera Phenix | DNA | 0.597976 | autophagy imaging |
| 46 | Cvamog4G3a2XYGM80000 | input_data_imaging_usecase/images/Timepoint001... | EI24KO | untreated | U2OS lcklip-mNeon mCherryLC3B EI24 KO clone 2 | DAPI | FOV1 | 20X | Opera Phenix | DNA | 0.597976 | autophagy imaging |
| 45 | Oww4y0yYuR8pxV9q0000 | input_data_imaging_usecase/images/Timepoint001... | EI24KO | untreated | U2OS lcklip-mNeon mCherryLC3B EI24 KO clone 2 | Alexa488 | FOV2 | 20X | Opera Phenix | LckLip-mNeon | 0.597976 | autophagy imaging |
Alternatively, we can query for the ULabel directly:
conditions = ln.ULabel.filter(
    links_artifact__feature__name="stimulation", artifacts__in=input_images
).distinct()

cell_line_clones = ln.ULabel.filter(
    links_artifact__feature__name="cell_line_clone", artifacts__in=input_images
).distinct()

FOVs = ln.ULabel.filter(
    links_artifact__feature__name="FOV", artifacts__in=input_images
).distinct()
By iterating through conditions, cell lines and FOVs, we should only have 3 images showing a single FOV to enable processing using scPortrait.
# Create artifact type feature and associated label
ln.Feature(name="artifact type", dtype=ln.ULabel).save()
ln.ULabel(name="scportrait config").save()

# Load config file for processing all datasets
config_file_af = ln.Artifact.connect("scportrait/examples").get(
    key="input_data_imaging_usecase/config.yml"
)

config_file_af.description = (
    "config for scportrait for processing of cells stained for autophagy markers"
)
config_file_af.save()

# Annotate the config file with the metadata relevant to the study
config_file_af.features.add_values(
    {"study": "autophagy imaging", "artifact type": "scportrait config"}
)
Show code cell output
! tip: pass `type` to map feature into a type hierarchy
! tip: pass `type` to map ulabel into a type hierarchy
→ Artifact input_data_imaging_usecase/config.yml: 1 transferred, 0 already on target
Process images with scPortrait
Let’s take a look at the processing of one example FOV.
# Get input images for one example FOV
condition, cellline, FOV = conditions[0], cell_line_clones[0], FOVs[0]

images = (
    input_images.filter(ulabels=condition)
    .filter(ulabels=cellline)
    .filter(ulabels=FOV)
    .distinct()
)

# Quick sanity check - all images should share metadata except channel/structure
values_to_ignore = ["channel", "imaged structure"]
features = images.first().features.get_values()
shared_features = {k: v for k, v in features.items() if k not in values_to_ignore}

for image in images:
    image_features = image.features.get_values()
    filtered_features = {
        k: v for k, v in image_features.items() if k not in values_to_ignore
    }
    assert shared_features == filtered_features

# Get image paths in correct channel order
input_image_paths = [
    images.filter(ulabels__name=channel).one().cache()
    for channel in ["DAPI", "Alexa488", "mCherry"]
]
# Create output directory and unique project ID
output_directory = "processed_data"
unique_project_id = f"{shared_features['cell_line_clone']}/{shared_features['stimulation']}/{shared_features['FOV']}".replace(
    " ", "_"
)
project_location = f"{output_directory}/{unique_project_id}/scportrait_project"

# Create directories
Path(project_location).mkdir(parents=True, exist_ok=True)

# Initialize the scPortrait project
project = Project(
    project_location=project_location,
    config_path=config_file_af.cache(),
    segmentation_f=CytosolSegmentationCellpose,
    extraction_f=HDF5CellExtraction,
    overwrite=True,
)

# Load images and process
project.load_input_from_tif_files(
    input_image_paths, overwrite=True, channel_names=["DAPI", "Alexa488", "mCherry"]
)
project.segment()
project.extract()
Show code cell output
Updating project config file.
/tmp/ipykernel_3194/1211438391.py:12: UserWarning: There is already a directory in the location path
  project = Project(
0%| | 0.00/25.3M [00:00<?, ?B/s]
1%| | 160k/25.3M [00:00<00:17, 1.52MB/s]
2%|▏ | 608k/25.3M [00:00<00:09, 2.83MB/s]
7%|▋ | 1.78M/25.3M [00:00<00:03, 6.55MB/s]
18%|█▊ | 4.61M/25.3M [00:00<00:01, 14.4MB/s]
49%|████▉ | 12.4M/25.3M [00:00<00:00, 35.4MB/s]
95%|█████████▌| 24.2M/25.3M [00:00<00:00, 59.6MB/s]
100%|██████████| 25.3M/25.3M [00:00<00:00, 38.6MB/s]
0%| | 0.00/3.54k [00:00<?, ?B/s]
100%|██████████| 3.54k/3.54k [00:00<00:00, 13.7MB/s]
/opt/hostedtoolcache/Python/3.12.15/x64/lib/python3.12/site-packages/torch/jit/_script.py:365: FutureWarning: `torch.jit.script_method` is deprecated. Please switch to `torch.compile` or `torch.export`.
  warnings.warn(
/opt/hostedtoolcache/Python/3.12.15/x64/lib/python3.12/site-packages/cellpose/dynamics.py:760: UserWarning: Sparse invariant checks are implicitly disabled. Memory errors (e.g. SEGFAULT) will occur when operating on a sparse tensor which violates the invariants, but checks incur performance overhead. To silence this warning, explicitly opt in or out. See `torch.sparse.check_sparse_tensor_invariants.__doc__` for guidance.  (Triggered internally at /__w/pytorch/pytorch/aten/src/ATen/Context.cpp:848.)
  coo = torch.sparse_coo_tensor(pt, torch.ones(pt.shape[1], device=pt.device, dtype=torch.int),
0%| | 0.00/25.3M [00:00<?, ?B/s]
1%| | 176k/25.3M [00:00<00:17, 1.47MB/s]
3%|▎ | 672k/25.3M [00:00<00:07, 3.24MB/s]
7%|▋ | 1.77M/25.3M [00:00<00:03, 6.53MB/s]
19%|█▉ | 4.92M/25.3M [00:00<00:01, 15.7MB/s]
41%|████ | 10.4M/25.3M [00:00<00:00, 29.7MB/s]
82%|████████▏ | 20.8M/25.3M [00:00<00:00, 51.2MB/s]
100%|██████████| 25.3M/25.3M [00:00<00:00, 37.0MB/s]
0%| | 0.00/3.54k [00:00<?, ?B/s]
100%|██████████| 3.54k/3.54k [00:00<00:00, 14.8MB/s]
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c721d5520>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c730585c0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15627d70>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c1c56e8a0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15687dd0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c156aa600>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c6d697b00>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c156ab3e0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c156b33e0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15507560>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c72b5d3d0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c1550bd10>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c1550fa40>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c72c22600>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15602a50>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15fa8380>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c156038f0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15b11850>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15b12600>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15ad9a60>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15b115b0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c72bdb830>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c159366f0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15880470>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15b7b3e0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15601190>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15f4ce60>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15fb7410>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15ad8890>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15ad8fe0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15bf5d00>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c158805c0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c157f0fe0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c1c11cd40>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c157f1730>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15e2b980>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15600890>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c157f2600>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15fb5160>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15b7a600>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c15f4fcb0>: None
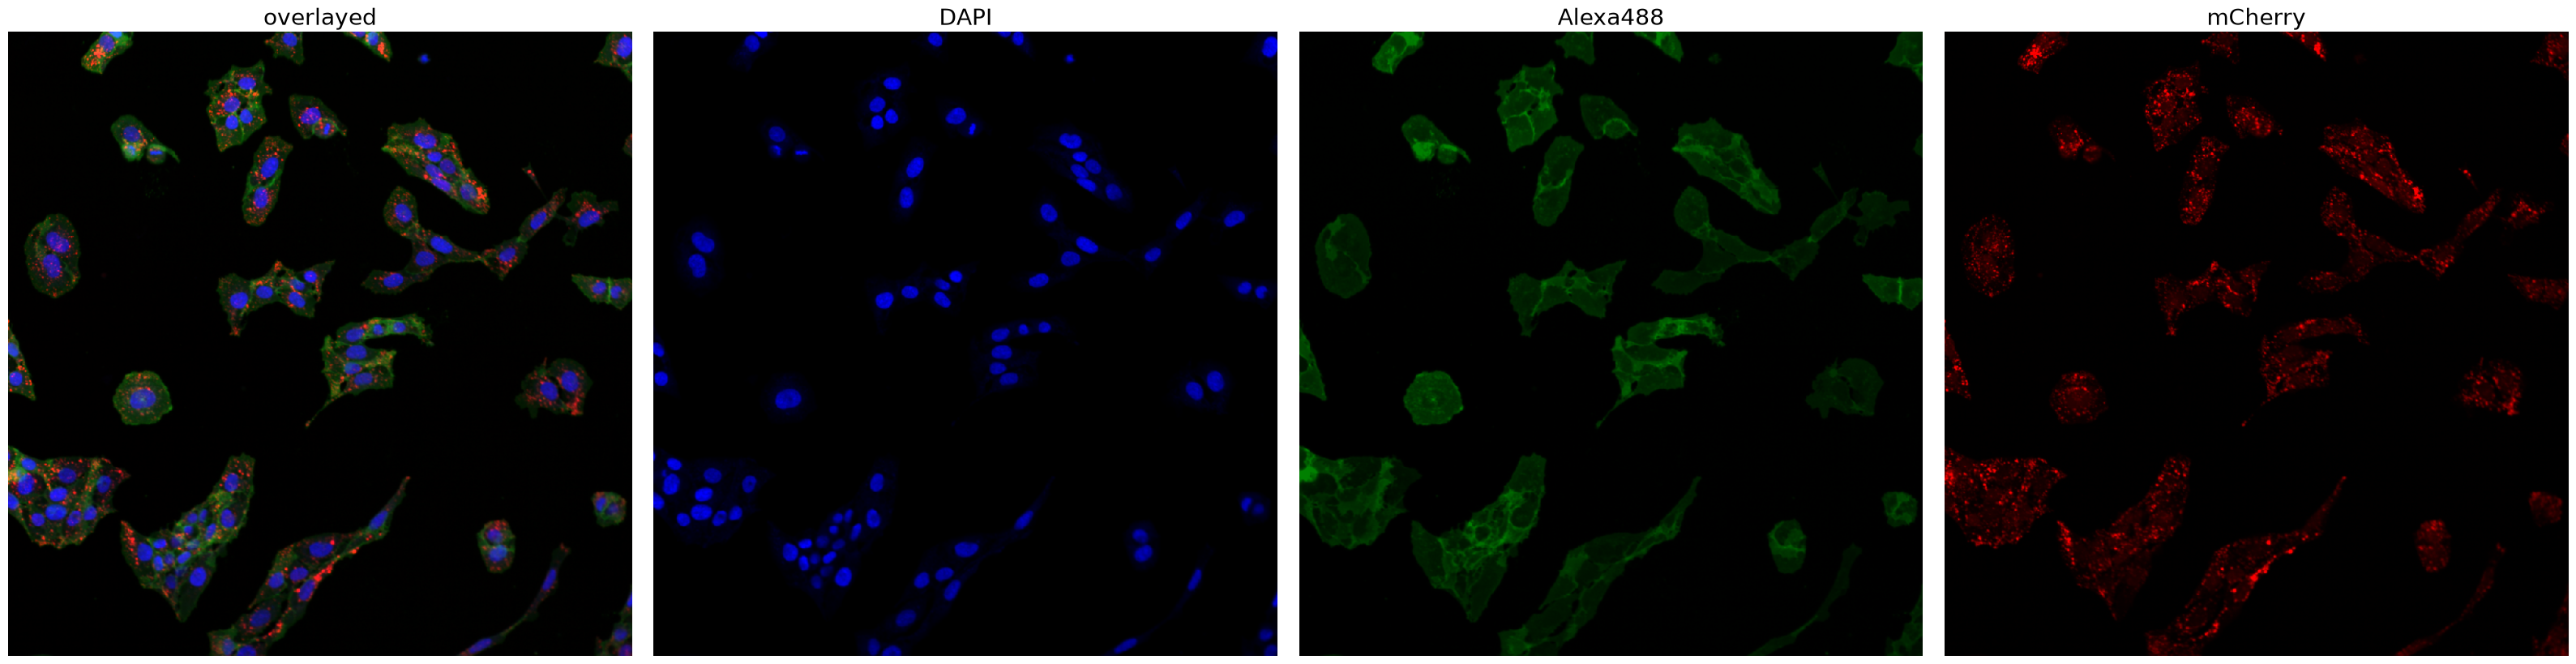
Let’s look at the input images we processed.
project.plot_input_image()
Show code cell output
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c1c0996d0>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c1c21d400>: None
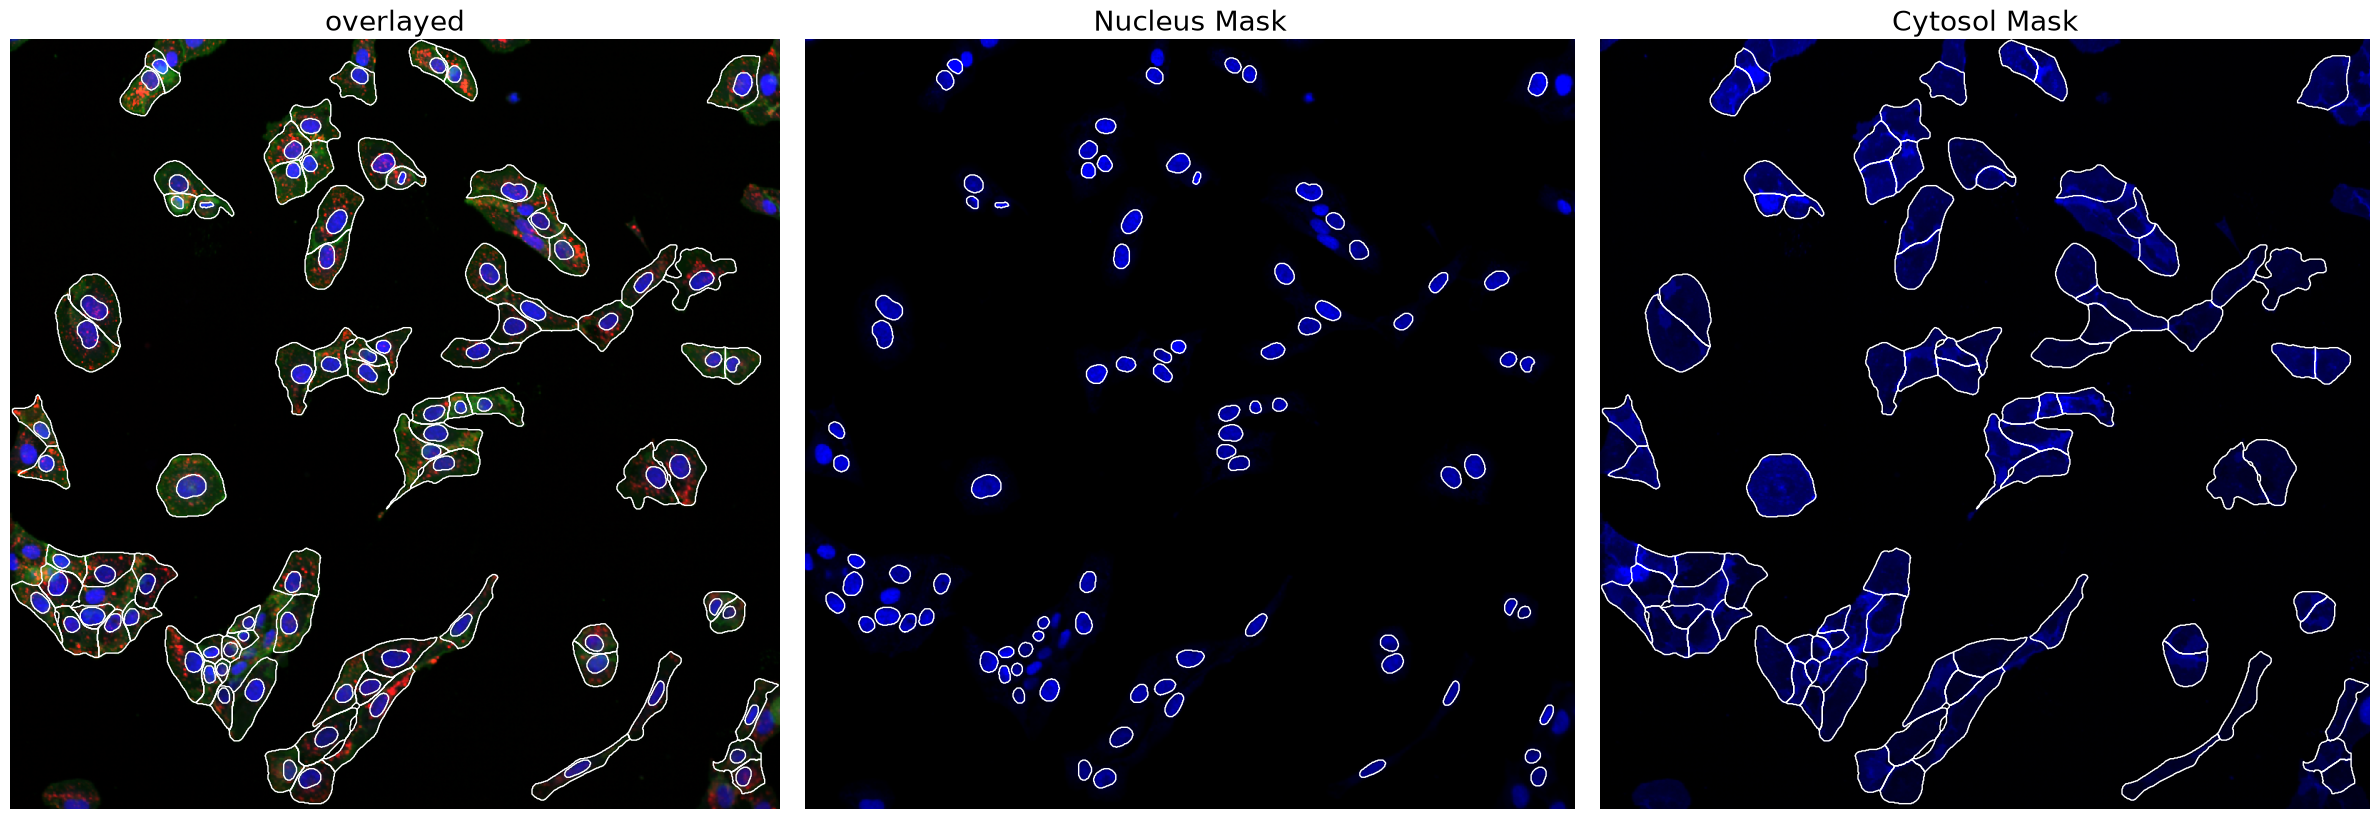
Now we can look at the results generated by scPortrait. First, the segmentation masks.
project.plot_segmentation_masks()
Show code cell output
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c729c2b10>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c1c728e00>: None
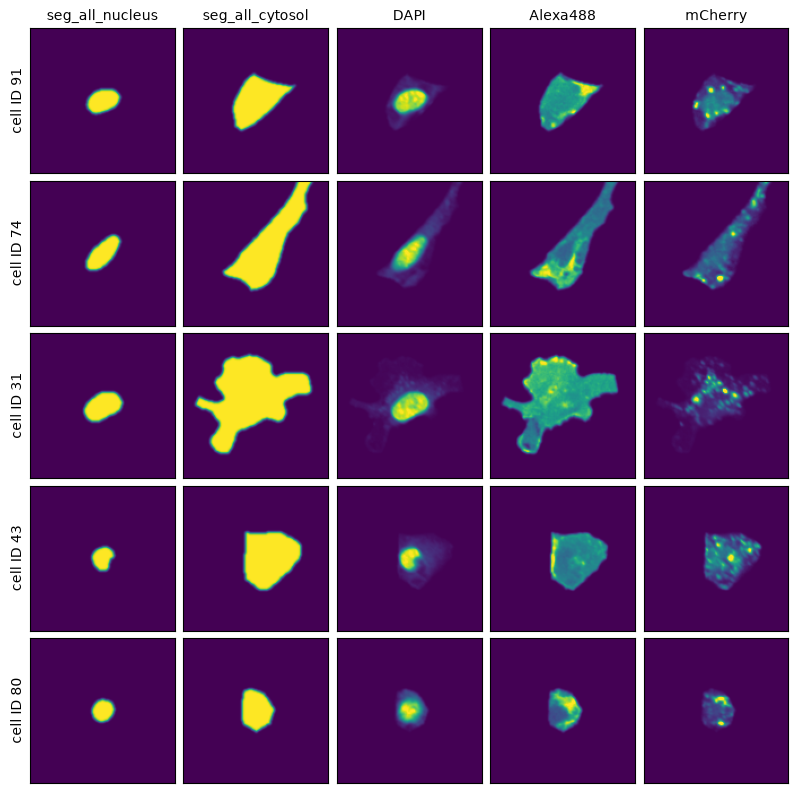
And then extraction results consisting of individual single-cell images over all of the channels.
project.plot_single_cell_images()
Show code cell output
Save and annotate results
Now we also want to save these results to the instance.
ln.Artifact.from_spatialdata(
    sdata=project.filehandler.get_sdata(),
    description="scportrait spatialdata object containing results of cells stained for autophagy markers",
    key=f"processed_data_imaging_use_case/{unique_project_id}/spatialdata.zarr",
).save()
Show code cell output
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c725a8890>: None
WARNING:ome_zarr.reader:no parent found for <ome_zarr.reader.Label object at 0x7f7c72651580>: None
Artifact(uid='Uwxrw38A5bZLWErc0000', key='processed_data_imaging_use_case/U2OS_lcklip-mNeon_mCherryLC3B_clone_1/14h_Torin-1/FOV1/spatialdata.zarr', description='scportrait spatialdata object containing results of cells stained for autophagy markers', suffix='.zarr', kind='dataset', otype='SpatialData', size=5806980, hash='fOxQvTiXkoKAUrE9NARA8Q', n_files=67, n_observations=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=3, schema_id=None, created_by_id=1, created_at=2026-10-21 07:44:24 UTC, is_locked=False, version_tag=None, is_latest=True)
# Define schemas for single-cell image dataset
schemas = {
    "obs": ln.Schema(
        name="single-cell image dataset schema obs",
        features=[
            ln.Feature(name="scportrait_cell_id", dtype="int", coerce_dtype=True).save()
        ],
    ).save(),
    "uns": ln.Schema(
        name="single-cell image dataset schema uns",
        features=[ln.Feature(name="single_cell_images", dtype=dict).save()],
    ).save(),
}

# Create composite schema
h5sc_schema = ln.Schema(
    name="single-cell image dataset",
    otype="AnnData",
    slots=schemas,
).save()
Show code cell output
! rather than passing a string 'int' to dtype, consider passing a Python object
! tip: pass `type` to map feature into a type hierarchy
! tip: pass `type` to map schema into a type hierarchy
! tip: pass `type` to map feature into a type hierarchy
! tip: pass `type` to map schema into a type hierarchy
! you are trying to create a schema with name='single-cell image dataset schema uns' but a record with similar name exists: 'single-cell image dataset schema obs'. Did you mean to load it?
! tip: pass `type` to map schema into a type hierarchy
! you are trying to create a schema with name='single-cell image dataset' but records with similar names exist: 'single-cell image dataset schema obs', 'single-cell image dataset schema uns'. Did you mean to load one of them?
/tmp/ipykernel_3194/1081745476.py:6: DeprecationWarning: `coerce_dtype` argument was renamed to `coerce` and will be removed in a future release.
  ln.Feature(name="scportrait_cell_id", dtype="int", coerce_dtype=True).save()
# Curate the AnnData object
curator = ln.curators.AnnDataCurator(project.h5sc, h5sc_schema)
curator.validate()

# Save artifact with annotations
artifact = curator.save_artifact(
    key=f"processed_data_imaging_use_case/{unique_project_id}/single_cell_data.h5ad"
)

# Add metadata and labels
annotation = shared_features.copy()
annotation["imaged structure"] = [
    ln.ULabel.connect("scportrait/examples").get(name=name)
    for name in ["LckLip-mNeon", "DNA", "mCherry-LC3B"]
]

artifact.features.add_values(annotation)
artifact.ulabels.add(ln.ULabel(name="scportrait single-cell images").save())
Show code cell output
→ returning schema with same hash: Schema(uid='sdI793aWKSAlqOSm', is_type=False, name='single-cell image dataset schema obs', description=None, n_members=1, coerce=None, flexible=False, itype='Feature', otype=None, suffix=None, hash='QQzSLHiRze0Fv-56VT3aHQ', minimal_set=True, ordered_set=False, maximal_set=False, branch_id=1, created_on_id=1, space_id=1, created_by_id=1, run_id=3, type_id=None, created_at=2026-10-21 07:44:24 UTC, is_locked=False)
→ returning schema with same hash: Schema(uid='sSOINEUjAlaGFKNL', is_type=False, name='single-cell image dataset schema uns', description=None, n_members=1, coerce=None, flexible=False, itype='Feature', otype=None, suffix=None, hash='XAzzn7eAFbT7W6yUoQ-8CA', minimal_set=True, ordered_set=False, maximal_set=False, branch_id=1, created_on_id=1, space_id=1, created_by_id=1, run_id=3, type_id=None, created_at=2026-10-21 07:44:24 UTC, is_locked=False)
! tip: pass `type` to map ulabel into a type hierarchy
To process all files in our dataset efficiently, we’ll create a custom image processing function.
We decorate this function with tracked() to track data lineage of the input and output artifacts.
The function will skip files that have already been processed and uploaded, improving processing time by avoiding redundant computations.
@ln.tracked()
def process_images(
    config_file_af: ln.Artifact,
    input_artifacts: Iterable[ln.Artifact],
    h5sc_schema: ln.Schema,
    output_directory: str,
) -> None:
    # Quick sanity check - all images should share metadata except channel/structure
    values_to_ignore = ["channel", "imaged structure"]
    first_features = input_artifacts.first().features.get_values()
    shared_features = {
        k: v for k, v in first_features.items() if k not in values_to_ignore
    }

    for artifact in input_artifacts:
        artifact_features = artifact.features.get_values()
        filtered_features = {
            k: v for k, v in artifact_features.items() if k not in values_to_ignore
        }
        assert shared_features == filtered_features

    # Create a unique project ID
    unique_project_id = f"{shared_features['cell_line_clone']}/{shared_features['stimulation']}/{shared_features['FOV']}".replace(
        " ", "_"
    )

    # Check if already processed
    base_key = f"processed_data_imaging_use_case/{unique_project_id}"
    try:
        ln.Artifact.connect("scportrait/examples").get(
            key=f"{base_key}/single_cell_data.h5ad"
        )
        ln.Artifact.connect("scportrait/examples").get(
            key=f"{base_key}/spatialdata.zarr"
        )
        print("Dataset already processed. Skipping.")
        return
    except ln.Artifact.DoesNotExist:
        pass

    # Get image paths in channel order
    input_image_paths = [
        input_artifacts.filter(ulabels__name=channel).one().cache()
        for channel in ["DAPI", "Alexa488", "mCherry"]
    ]

    # Setup and process project
    project_location = f"{output_directory}/{unique_project_id}/scportrait_project"
    Path(project_location).mkdir(parents=True, exist_ok=True)

    project = Project(
        project_location=project_location,
        config_path=config_file_af.cache(),
        segmentation_f=CytosolSegmentationCellpose,
        extraction_f=HDF5CellExtraction,
        overwrite=True,
    )

    project.load_input_from_tif_files(
        input_image_paths, overwrite=True, channel_names=["DAPI", "Alexa488", "mCherry"]
    )
    project.segment()
    project.extract()

    # Save single-cell images
    curator = ln.curators.AnnDataCurator(project.h5sc, h5sc_schema)
    curator.validate()
    artifact = curator.save_artifact(key=f"{base_key}/single_cell_data.h5ad")

    annotation = shared_features.copy()
    annotation["imaged structure"] = [
        ln.ULabel.connect("scportrait/examples").get(name=name)
        for name in ["LckLip-mNeon", "DNA", "mCherry-LC3B"]
    ]

    artifact.features.add_values(annotation)
    artifact.ulabels.add(ln.ULabel.get(name="scportrait single-cell images"))

    # Save SpatialData object
    ln.Artifact.from_spatialdata(
        sdata=project.filehandler.get_sdata(),
        description="scportrait spatialdata object containing results of cells stained for autophagy markers",
        key=f"{base_key}/spatialdata.zarr",
    ).save()
Show code cell output
/tmp/ipykernel_3194/2587565420.py:1: DeprecationWarning: Use step instead of tracked, tracked will be removed in the future.
  @ln.tracked()
Now we are ready to process all of our input images and upload the generated single-cell image datasets back to our instance.
for condition in conditions:
    for cellline in cell_line_clones:
        for FOV in FOVs:
            images = (
                input_images.filter(ulabels=condition)
                .filter(ulabels=cellline)
                .filter(ulabels=FOV)
                .distinct()
            )

            if images:
                process_images(
                    config_file_af,
                    input_artifacts=images,
                    h5sc_schema=h5sc_schema,
                    output_directory=output_directory,
                )
Show code cell output
→ ignoring transform with same filename in different folder:
    56IaWPrFDRtQ0000 → sc-imaging2.ipynb
→ created Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('A6cRes5aKEabNTbm', entrypoint='process_images') at 2026-10-21 07:44:24 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[Md4OouMExlWS2YfZ0000]', 'Artifact[CiQYTBNZrj0CPejK0000]', 'Artifact[YGiNq6DPfIEjtt9j0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('RlcdtH96EGZX2qlO', entrypoint='process_images') at 2026-10-21 07:44:25 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[KKbVRkOjQ1jdA2fx0000]', 'Artifact[W6tzE7JNiM80Ruho0000]', 'Artifact[uuh41FAHEz0ASL2N0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('4sskn67SDWRu5eQg', entrypoint='process_images') at 2026-10-21 07:44:26 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[yiIMSAddDWgLgki70000]', 'Artifact[DEzw4QQAsjVZ010b0000]', 'Artifact[hbVyCGFARHU91Kax0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('EFaYSBnsS1CZgyFz', entrypoint='process_images') at 2026-10-21 07:44:26 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[2ie2Kjzn1O7UYhuq0000]', 'Artifact[fOQSb7JCK67aeN6a0000]', 'Artifact[qHQpdWcFu7FzF6l50000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('HurdtRkcnxDIDXAB', entrypoint='process_images') at 2026-10-21 07:44:27 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[jVytS8AyAHmHkYR30000]', 'Artifact[cw4F6bUB9zuMthCY0000]', 'Artifact[7TZGXvbA0JLL68hR0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('EKwEqky8QClwsjlq', entrypoint='process_images') at 2026-10-21 07:44:27 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[vCVbKkzz4CnJPPKF0000]', 'Artifact[5kMhlcDNek4RMeQF0000]', 'Artifact[9BmbViqMmlVhpfS00000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('MsujlFCi8GQ9QNxp', entrypoint='process_images') at 2026-10-21 07:44:28 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[OS0wBE7bviIlW7qj0000]', 'Artifact[ixOpuSTsyrPXdYuA0000]', 'Artifact[6uMjKAk1aYlAV7Cf0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('Ckng34oVO6UCEqIx', entrypoint='process_images') at 2026-10-21 07:44:28 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[9ZVngbl0JUS0XdZ70000]', 'Artifact[IzP3IAwIhmM7OORD0000]', 'Artifact[RRVS8qVx3VSw02Xu0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('UCX6uRFov1wwXAoQ', entrypoint='process_images') at 2026-10-21 07:44:29 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[Gtwi9Pcyx8maQEWB0000]', 'Artifact[sHHpiiFYWsIXMZNV0000]', 'Artifact[hNMkrIHce1XrLZHY0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('WBA3CKLCNkho6B1K', entrypoint='process_images') at 2026-10-21 07:44:30 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[nSZhAypqiNZ2Ylbe0000]', 'Artifact[jzqxtoduIJ3hCbB40000]', 'Artifact[M06liaIzh2OVEuJ40000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('xZuFcUKuMWJ23WIS', entrypoint='process_images') at 2026-10-21 07:44:30 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[mXWwV1x42Jz9RoSO0000]', 'Artifact[gj0HHnoVpEqbaUJb0000]', 'Artifact[1XnEyqVt6UGXCTmV0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('Tpp1LAlfgRAuZCJz', entrypoint='process_images') at 2026-10-21 07:44:31 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[Ov8FnKzHMNY0XVJa0000]', 'Artifact[Lwk8shsYe0V5bMgd0000]', 'Artifact[YuyVn060M4FxATPz0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('4zr3w8PKMVIZJy63', entrypoint='process_images') at 2026-10-21 07:44:31 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[ThuJnRAhqkp54kyU0000]', 'Artifact[PquYNyshQTDd24Vw0000]', 'Artifact[8SFUmW0RhBNySxBO0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('lIGIhoPU2QUjIOXs', entrypoint='process_images') at 2026-10-21 07:44:32 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[h4EKWveW36LIzXez0000]', 'Artifact[fdem35nw5ztUnEIM0000]', 'Artifact[VkmKLUCaMsYFCuGE0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('ch29CaOutOXesRHF', entrypoint='process_images') at 2026-10-21 07:44:33 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[QDPX1ljp0eCMz80o0000]', 'Artifact[Cvamog4G3a2XYGM80000]', 'Artifact[6uUjyphUD4D1Hixc0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
→ loaded Transform('4fn27CXsg5g00000', key='sc-imaging2.ipynb'), started new Run('adirAvVzFt7wj5i8', entrypoint='process_images') at 2026-10-21 07:44:33 UTC
→ params: config_file_af='Artifact[voi8szTkmKPiahUA0000]', input_artifacts=['Artifact[Oww4y0yYuR8pxV9q0000]', 'Artifact[AhBvnNKg5yJcG6LU0000]', 'Artifact[AVRTVX9gEu4LrTAP0000]'], h5sc_schema='Schema[YQ4n8Fl5yzExC0t7]', output_directory='processed_data'
Dataset already processed. Skipping.
example_artifact = ln.Artifact.filter(
    ulabels=ln.ULabel.get(name="scportrait single-cell images")
).first()

example_artifact.view_lineage()
Show code cell output

ln.finish()
Show code cell output
→ finished Run('AOhp17JHTOVUi0sf') after 1m at 2026-10-21 07:44:34 UTC